diff --git a/blog/en/blog/2025/02/24/apisix-ai-gateway-features.md b/blog/en/blog/2025/02/24/apisix-ai-gateway-features.md
index 46b6602c92c03..30e459f76054d 100644
--- a/blog/en/blog/2025/02/24/apisix-ai-gateway-features.md
+++ b/blog/en/blog/2025/02/24/apisix-ai-gateway-features.md
@@ -4,136 +4,93 @@ keywords:
- APISIX
- AI gateway
- LLM API
- - security protection
- token rate limiting
- - smart traffic management
+ - model routing
- multi-LLM proxy
- - cloud-native API
-description: "Learn how Apache APISIX AI Gateway handles LLM traffic with model routing, token rate limiting, retry and fallback, prompt controls, and observability."
+ - prompt controls
+ - AI response caching
+ - semantic routing
+ - AI observability
+description: "Learn how Apache APISIX AI Gateway handles LLM traffic with model proxying, configured routing, caching, token limits, prompt controls, RAG, and observability."
tags: [Ecosystem]
image: https://static.api7.ai/uploads/2025/03/07/Qs4WrU0I_apisix-ai-gateway.webp
---
->This article will provide an in-depth look at the AI gateway features of the current and upcoming versions of APISIX. As a multifunctional API and AI gateway, Apache APISIX offers efficient and secure LLM API calls for AI applications.
+The [Apache APISIX AI Gateway](/ai-gateway/) applies model proxying, configured routing, response caching, token limits, prompt controls, retrieval, and gateway-level observability to LLM traffic through open-source plugins. This article maps those capabilities to the APISIX plugins that implement them.
-## Introduction: The Rise of AI Agents and the Evolution of AI Gateway
+## Why AI Traffic Needs Additional Gateway Controls
-In recent years, AI agents such as AutoGPT, Chatbots, and AI Assistants have seen rapid development. These applications rely heavily on API calls to large language models (LLMs), which have brought about challenges considering high concurrency, cost control, and security.
+LLM requests share many requirements with ordinary API traffic, including authentication, routing, rate limiting, resilience, and observability. They also introduce provider-specific request formats, token-based consumption, long-running streamed responses, and prompt-processing requirements.
-Traditional API gateways primarily serve Web APIs and microservices and are not optimized for the unique needs of AI applications. This has led to the emergence of the concept of AI gateway. An AI gateway needs to provide enhanced capabilities in the following areas:
+Apache APISIX handles these concerns on the network path between an authorized application and configured model endpoints. It does not select tools, orchestrate agent workflows, evaluate answer quality, or replace application-level authorization. Those responsibilities remain in the application and AI platform layers.
-- **Multi-LLM Proxy**: Support for multiple LLM providers to avoid vendor lock-in.
-- **Token Rate Limiting**: Prevent API abuse and optimize cost management.
-- **Security Protection**: Including prompt filtering and content moderation to ensure compliance of AI applications.
-- **Smart Traffic Management**: Dynamically adjust LLM weights based on cost, latency, and stability.
+## Proxy Requests to Supported Model Providers
-Apache APISIX is not only an API gateway but also an AI gateway through its plugins, helping AI applications call LLM APIs more efficiently and securely.
+The [`ai-proxy`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy/) plugin forwards requests to documented model providers and OpenAI-compatible endpoints. It can transform supported request formats, attach provider credentials from gateway configuration, and expose a consistent application-facing endpoint.
-## LLM Proxy: Efficient Management of Multiple LLM Backends
+Provider compatibility depends on the selected APISIX provider type and the upstream API. Teams should verify request and response fields for each provider instead of assuming every model implements the same interface.
-AI applications typically do not rely on a single LLM provider but need to dynamically select the best model based on requirements. For example:
+## Configure Multi-Model Routing and Resilience
-- Using OpenAI GPT-4 for general text generation and Claude for legal document processing.
-- Switching between Mistral and Gemini to optimize cost and throughput.
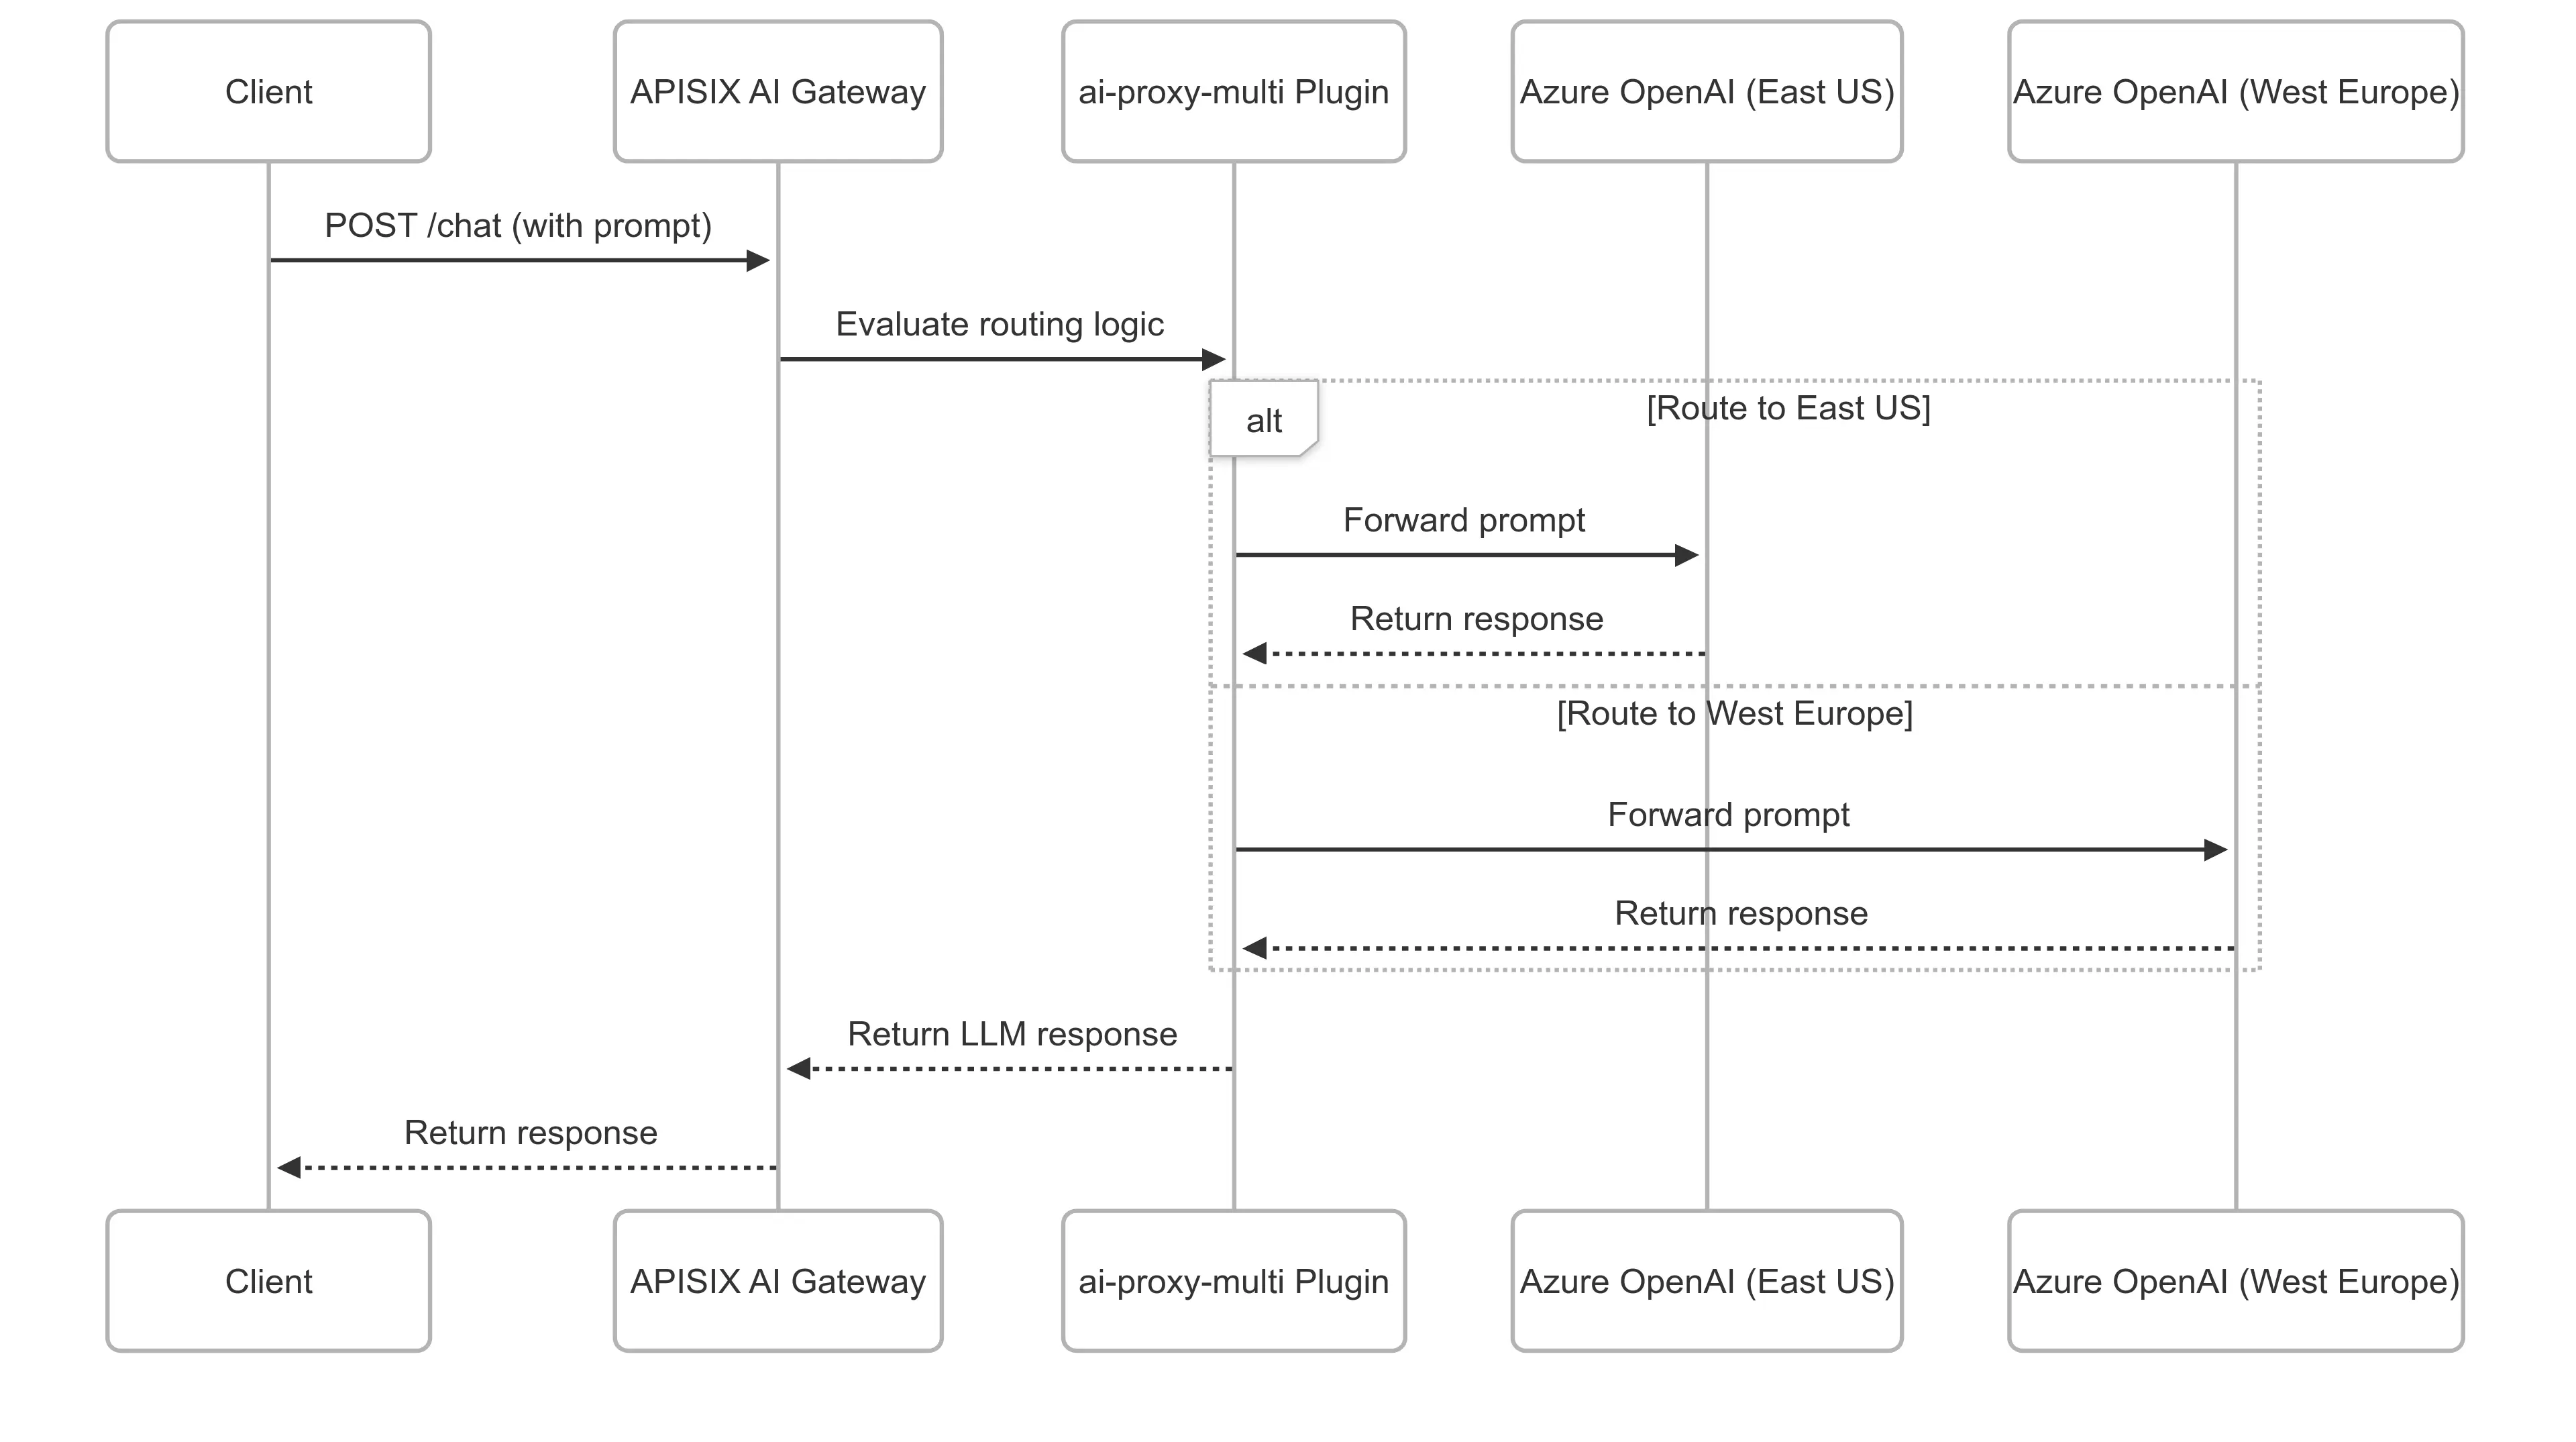
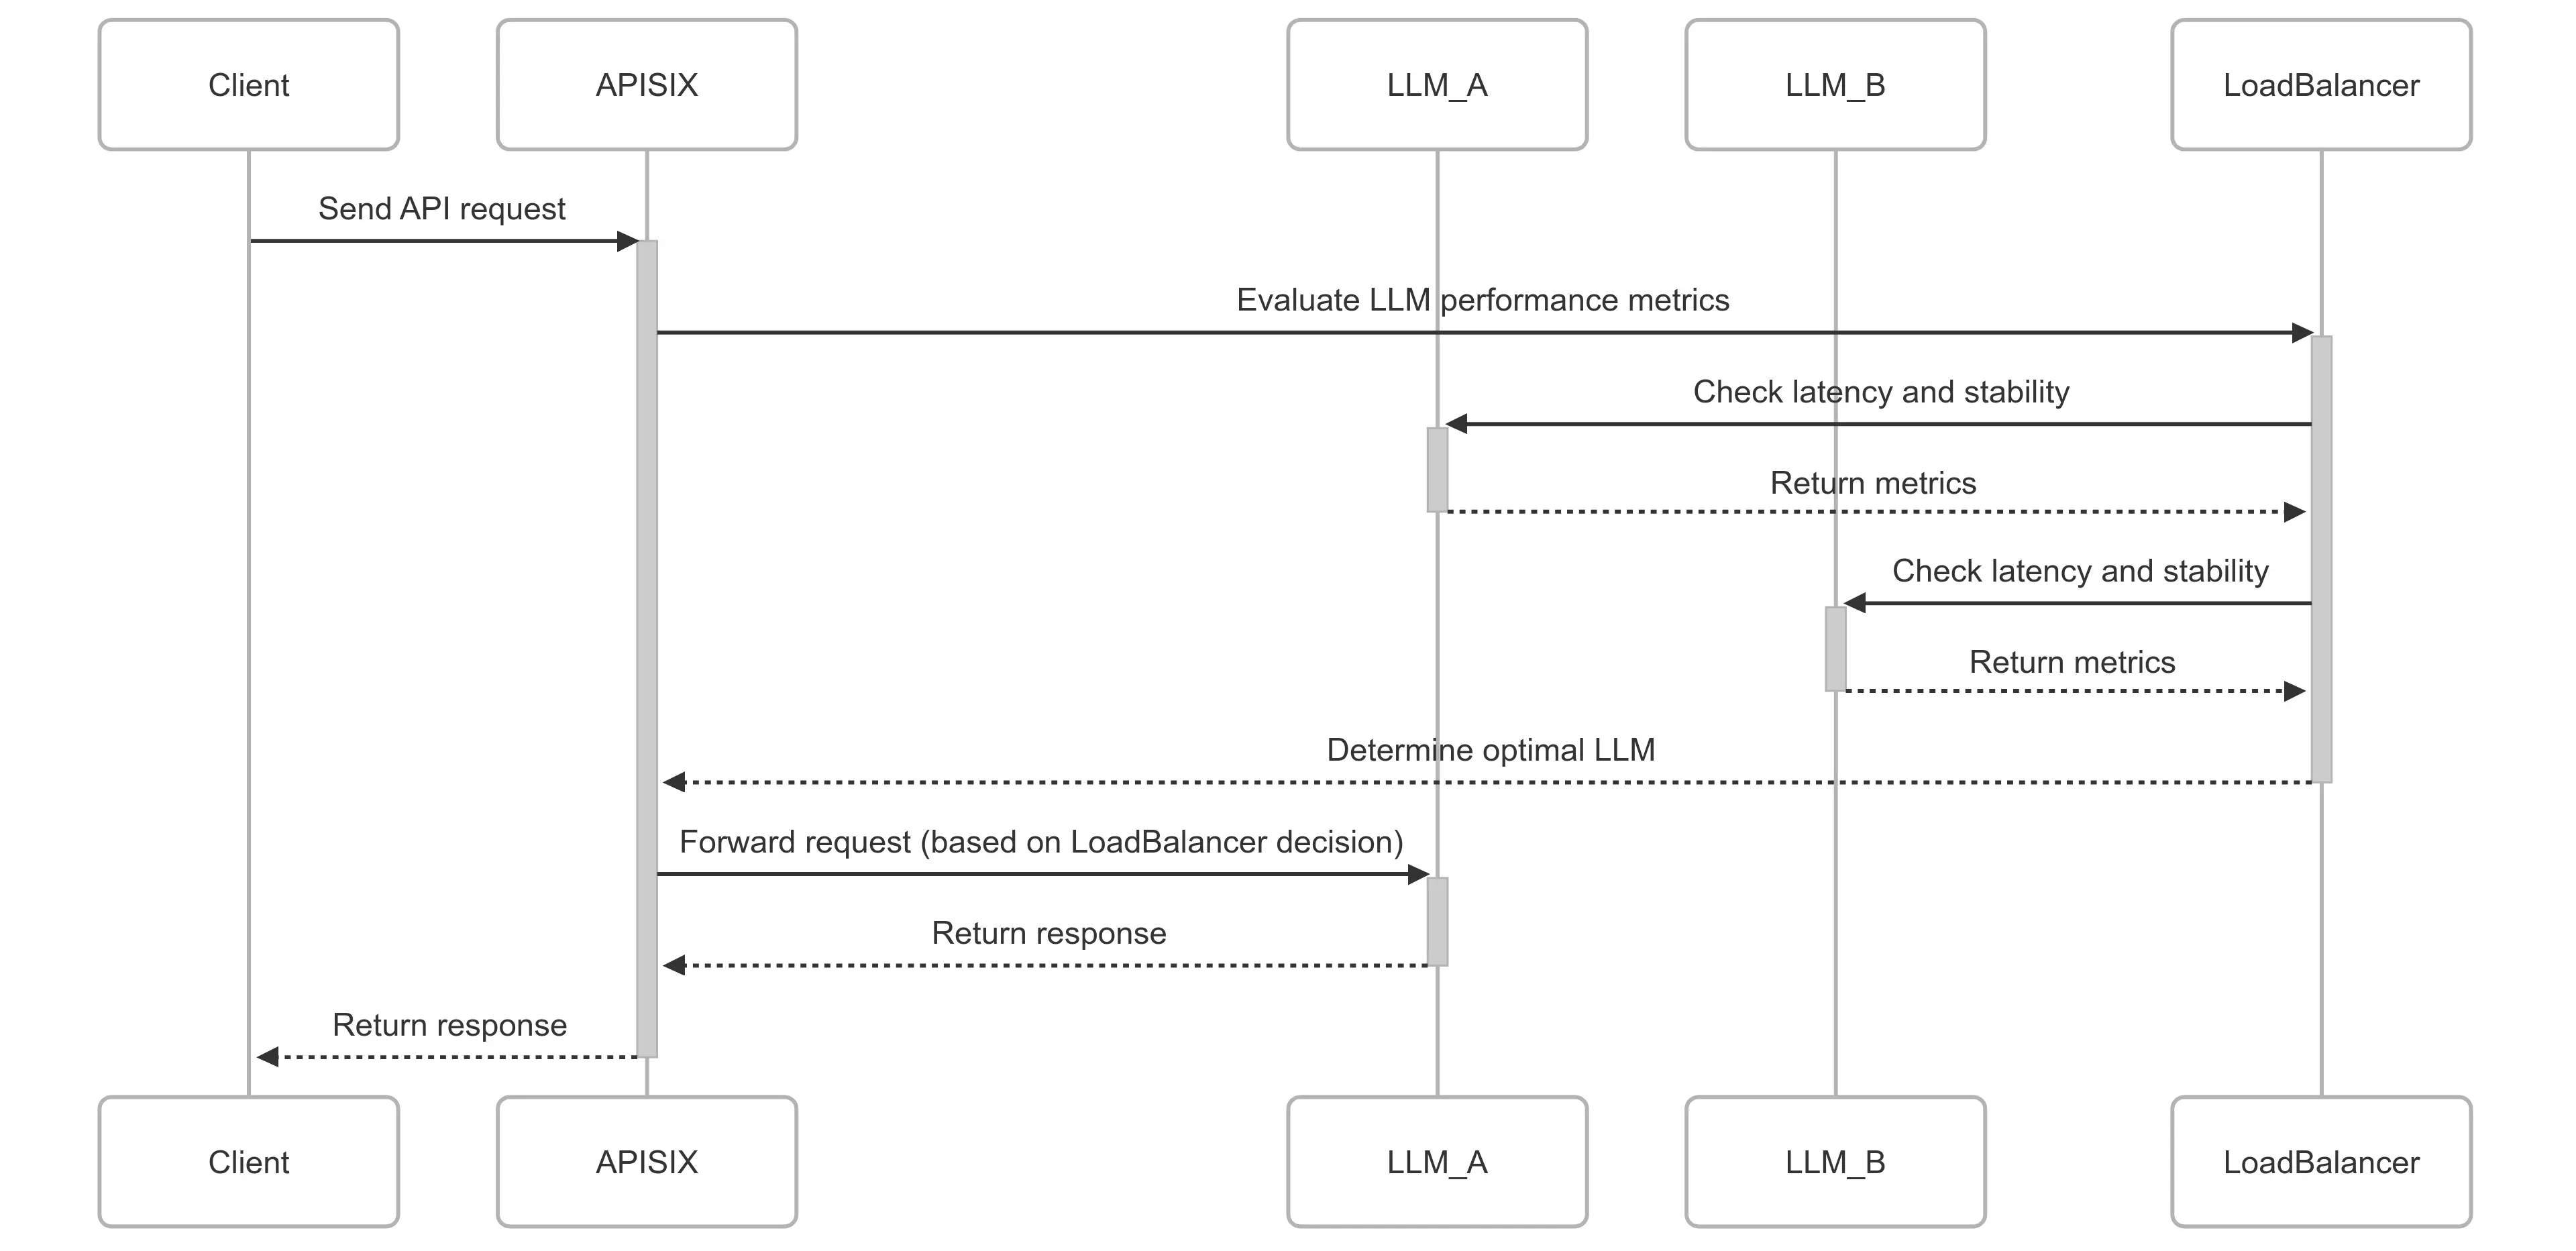
+The [`ai-proxy-multi`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy-multi/) plugin distributes requests across configured model instances. Its documented routing policies include weighted round robin and consistent hashing, with optional health checks, bounded retries, and fallback behavior.
-**Apache APISIX's LLM Proxy offers the following capabilities:**
+APISIX 3.18 also supports a semantic routing algorithm. Operators provide example prompts for each instance and configure an embedding service; the plugin compares the incoming prompt with those examples and selects the closest instance that clears the configured threshold. This is configured intent routing, not automatic optimization based on model cost, latency, answer quality, or business outcomes.
-✅ Support for Multiple LLM Providers: Including OpenAI, DeepSeek, Claude, Mistral, Gemini, etc., to avoid vendor lock-in.
+Semantic routing does not participate in health checks, retry, or the normal fallback strategy. Its designated fallback is used only when no instance clears the similarity threshold or the embedding request fails. Weighted round robin and consistent hashing continue to use their documented resilience options.
-✅ LLM Weight and Priority Management: Adjust traffic distribution based on business needs.
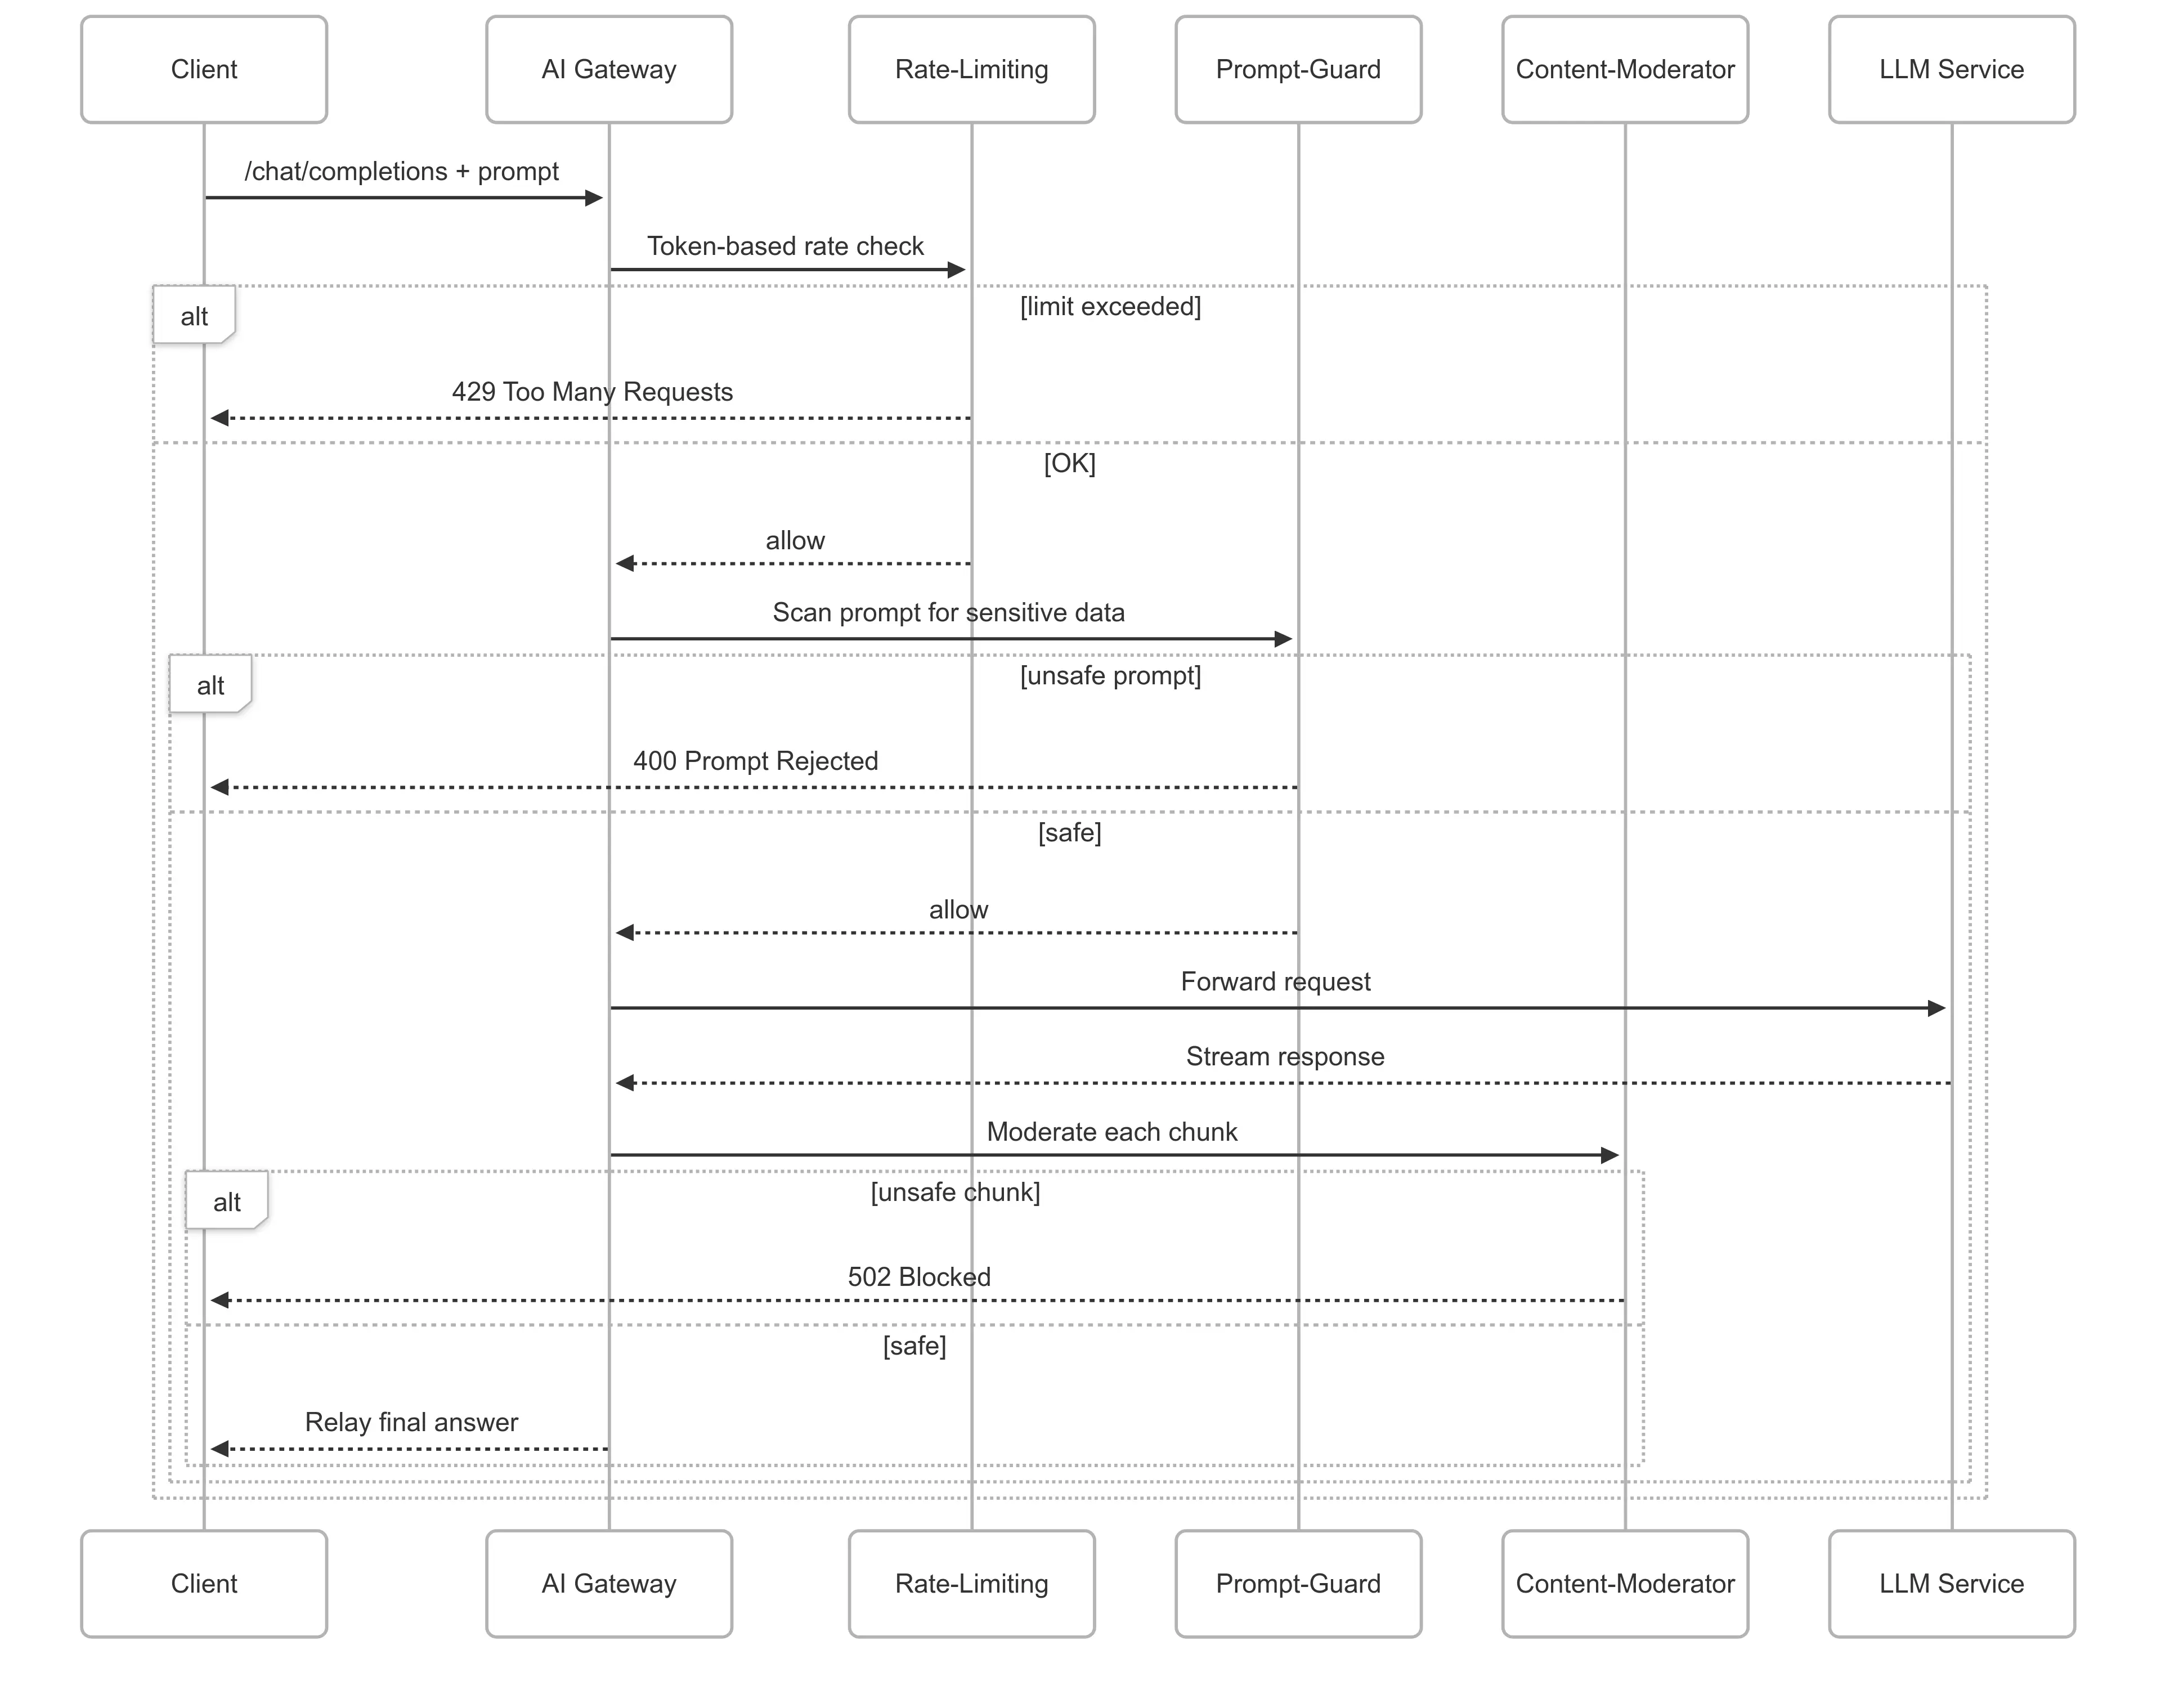
+
-✅ Multi-LLM Load Balancing: Dynamically adjust LLM weights based on latency, cost, and stability.
+These controls can reduce provider-specific routing logic in applications, but they do not guarantee uninterrupted service. Availability still depends on healthy upstreams, network conditions, timeouts, retry limits, and the configured fallback path.
-✅ Retry and Fallback Mechanisms: Ensure business continuity if an LLM API fails.
+## Enforce Token-Based Usage Limits
-✅ Load Balancing Across Different Providers of the Same LLM:
+LLM requests can consume very different numbers of prompt and completion tokens. The [`ai-rate-limiting`](https://apisix.apache.org/docs/apisix/plugins/ai-rate-limiting/) plugin applies limits based on token consumption rather than request count alone.
-For example:
+APISIX supports local and Redis-backed counters for this plugin. Operators can scope policies through gateway configuration and choose limits appropriate for their applications. The plugin records provider-reported usage after a response and rejects later requests once the observed counter has consumed the quota. A large response or concurrent requests can therefore take observed usage beyond the configured limit before later requests are rejected. Model pricing, budgets, billing, and chargeback remain external responsibilities.
-- Privately deployed DeepSeek.
-- Official DeepSeek API.
-- DeepSeek API from Volcano Engine
+## Cache Completed LLM Responses
-Users can flexibly allocate traffic weights among different DeepSeek providers based on latency, stability, and price to achieve the best calling strategy.
+The [`ai-cache`](https://apisix.apache.org/docs/apisix/plugins/ai-cache/) plugin works with `ai-proxy` or `ai-proxy-multi` to cache completed LLM responses in Redis. Exact matching is enabled by default. Teams can optionally add semantic matching, which requires a Redis deployment that provides the required Redis Search commands and a configured embedding service. The [Redis integration guide](https://apisix.apache.org/integrations/redis/) pins Redis Open Source 8.10.1 for its companion lab; earlier Redis Open Source or Redis Stack releases should be pinned and tested explicitly.
-These capabilities enable AI applications to adapt flexibly to different LLMs, improve reliability, and reduce API calling costs.
+Streaming responses are written only after the terminal event is received. Interrupted streams are not cached, so the plugin does not replay partial responses. Cache eligibility, isolation, expiration, bypass rules, and semantic thresholds still need to be configured for the application's data and freshness requirements.
-
+Cache entries are scoped by Route by default, not by Consumer. On a multi-tenant Route, authenticate each tenant and enable `cache_key.include_consumer` to scope entries by Consumer identity. If tenant identity comes from another trusted server-side source, add its NGINX variable through `cache_key.include_vars`. Unauthenticated traffic still shares the Route-level cache unless a trusted server-side variable is included; a client-controlled header alone is not a tenant boundary.
-## AI Security Protection: Ensuring Safe and Compliant Use of AI
+## Apply Purpose-Specific Prompt and Content Controls
-AI APIs may involve sensitive data, misleading information, and potential misuse. Therefore, an AI gateway needs to provide security at multiple levels.
+APISIX provides separate plugins for different kinds of prompt processing:
-**The AI security capabilities provided by Apache APISIX include:**
+- [`ai-prompt-template`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-template/) applies predefined prompt templates.
+- [`ai-prompt-decorator`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-decorator/) adds configured content before or after a prompt.
+- [`ai-prompt-guard`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-guard/) allows or denies prompts using configured regular-expression patterns.
+- [`ai-aws-content-moderation`](https://apisix.apache.org/docs/apisix/plugins/ai-aws-content-moderation/) integrates with Amazon Comprehend for its documented moderation flow.
+- [`ai-aliyun-content-moderation`](https://apisix.apache.org/docs/apisix/plugins/ai-aliyun-content-moderation/) integrates with Alibaba Cloud content moderation for its documented flow.
+- [`ai-lakera-guard`](https://apisix.apache.org/docs/apisix/plugins/ai-lakera-guard/) integrates the Lakera Guard v2 API to inspect supported LLM requests, responses, or both when used with `ai-proxy` or `ai-proxy-multi`.
-✅ **AI RAG (Retrieval-Augmented Generation)**: Supports enterprise-owned knowledge bases to reduce LLM hallucinations and improve output reliability.
+These controls have different scopes and failure modes. Pattern checks and provider-specific moderation do not guarantee that content is safe or compliant. Teams still need application authorization, data classification, secrets management, provider governance, and human review where required.
-✅ **Prompt Guard**: Automatically intercepts sensitive, illegal, and inappropriate prompts to prevent malicious use by users.
+## Add a Documented RAG Retrieval Step
-✅ **Prompt Decorator**: Automatically adds content before and after user input to enhance the quality of LLM-generated content.
+The [`ai-rag`](https://apisix.apache.org/docs/apisix/plugins/ai-rag/) plugin implements the retrieval flow currently documented for Azure OpenAI embeddings and Azure AI Search. It retrieves relevant context and adds that context to a supported model request.
-✅ **Prompt Template**: Makes it easier for users to reuse standardized prompts and improve interaction experience.
+This can centralize the documented retrieval step for compatible deployments. It is not a generic connector for every knowledge base, and it does not evaluate factual accuracy or eliminate hallucinations.
-✅ **Response Filtering & Moderation**: Intercepts sensitive or non-compliant AI-generated content.
+## Observe AI Traffic at the Gateway
-✅ **Logging & Auditing**: Provides complete API request logs for compliance audits.
+When AI proxy logging is enabled, APISIX can record model information, request duration, prompt and response token counts, and time to first token when the upstream response exposes those values. Existing logging and observability plugins can export gateway data to the team's monitoring stack.
-These security measures ensure that AI applications meet enterprise-level security requirements and avoid compliance risks due to misleading AI content.
+Gateway telemetry covers requests that pass through APISIX. It complements application traces, provider-side monitoring, user feedback, and model-quality evaluation; it does not replace them.
-## Token Observability and Management: Preventing High Bills Due to API Abuse
+## Use API and AI Controls in One Gateway
-Calling LLM APIs consumes tokens, and API abuse can lead to significant costs. Apache APISIX provides fine-grained token monitoring and management mechanisms.
+Apache APISIX can apply its existing routing, authentication, traffic management, and observability capabilities alongside AI-specific plugins. This lets teams operate API and configured model traffic through one open-source gateway when that architecture fits their requirements.
-**The token management capabilities of Apache APISIX include:**
-
-✅ Token Rate Limiting by Route/Service/Consumer/Consumer Group/Custom Dimension
-
-✅ Support for Multiple Rate Limiting Modes:
-
-- Single-machine vs. cluster rate limiting to accommodate different scales of AI API services.
-- Fixed time window vs. sliding time window to flexibly control API rates.
-
-✅ Different Rate Limiting Policies for Different LLMs: Prevent cost overruns.
-
-Through Apache APISIX, enterprises can achieve fine-grained management of token resources and prevent high bills due to API abuse.
-
-## Smart Routing: Dynamic Traffic Management for AI APIs
-
-
-
-During AI API calls, different tasks may require different LLMs. For example:
-
-- Code generation requests → sent to GPT-4 or DeepSeek.
-- Long-form summarization tasks → sent to Claude.
-- General conversations → sent to GPT-3.5 or Gemini.
-
-**The smart routing capabilities of Apache APISIX include:**
-
-✅ Context-Aware Routing Based on Request Content:
-
-- Select the optimal LLM based on prompt type.
-- Allocate different models (GPT-4 Turbo vs. GPT-3.5) based on user level (paid vs. free users).
-
-✅ Response Caching: Reduce redundant API calls and improve response speed.
-
-These capabilities help AI APIs run more efficiently, reduce API latency, and increase throughput.
+The practical value comes from explicit, reviewable policies rather than autonomous decision-making. Teams configure the providers, routes, cache policy, limits, prompt controls, retrieval service, and observability integrations that APISIX should use.
## Conclusion
-With the rapid development of AI technology, API gateways also need to evolve to meet the unique needs of AI applications. Apache APISIX, with its LLM Proxy, token rate limiting, security protection, and smart routing features, has become the best choice for an AI gateway.
-
-**The core advantages of Apache APISIX compared to traditional API gateways are:**
-
-🚀 Support for Multiple LLM Providers: Avoid vendor lock-in.
-
-⚡️ Smart Traffic Scheduling: Dynamic load balancing to improve API reliability.
-
-🔒 Built-in Security Capabilities: Including prompt protection and content moderation to ensure secure and compliant AI APIs.
-
-💰 Token Rate Limiting: Prevent high bills due to API abuse.
-
-📊 High-performance Architecture: Meet the high concurrency needs of AI applications.
+Apache APISIX adds AI traffic controls through focused plugins: provider proxying, configured multi-model and semantic routing, response caching, bounded retries and fallback, token-based limits, prompt processing, external moderation integrations, a documented Azure RAG flow, and gateway-level telemetry.
-If you are building AI-related applications and want to have both a powerful API gateway and AI gateway, give Apache APISIX a try!
+Use each capability within its documented boundary. APISIX manages traffic to model services; the surrounding application stack continues to own business authorization, agent orchestration, workflow state, model evaluation, and compliance decisions.
diff --git a/blog/en/blog/2025/03/06/what-is-an-ai-gateway.md b/blog/en/blog/2025/03/06/what-is-an-ai-gateway.md
index b0eaed0eb5a14..a2856fce72c75 100644
--- a/blog/en/blog/2025/03/06/what-is-an-ai-gateway.md
+++ b/blog/en/blog/2025/03/06/what-is-an-ai-gateway.md
@@ -23,112 +23,94 @@ tags: [Ecosystem]
image: https://static.api7.ai/uploads/2025/03/07/1W9olFmu_what-is-ai-gateway.webp
---
->This article will explore how AI gateway address pressing API gateway concerns. Let's discover how AI gateways unlock the full potential of AI, turning challenges into opportunities for growth.
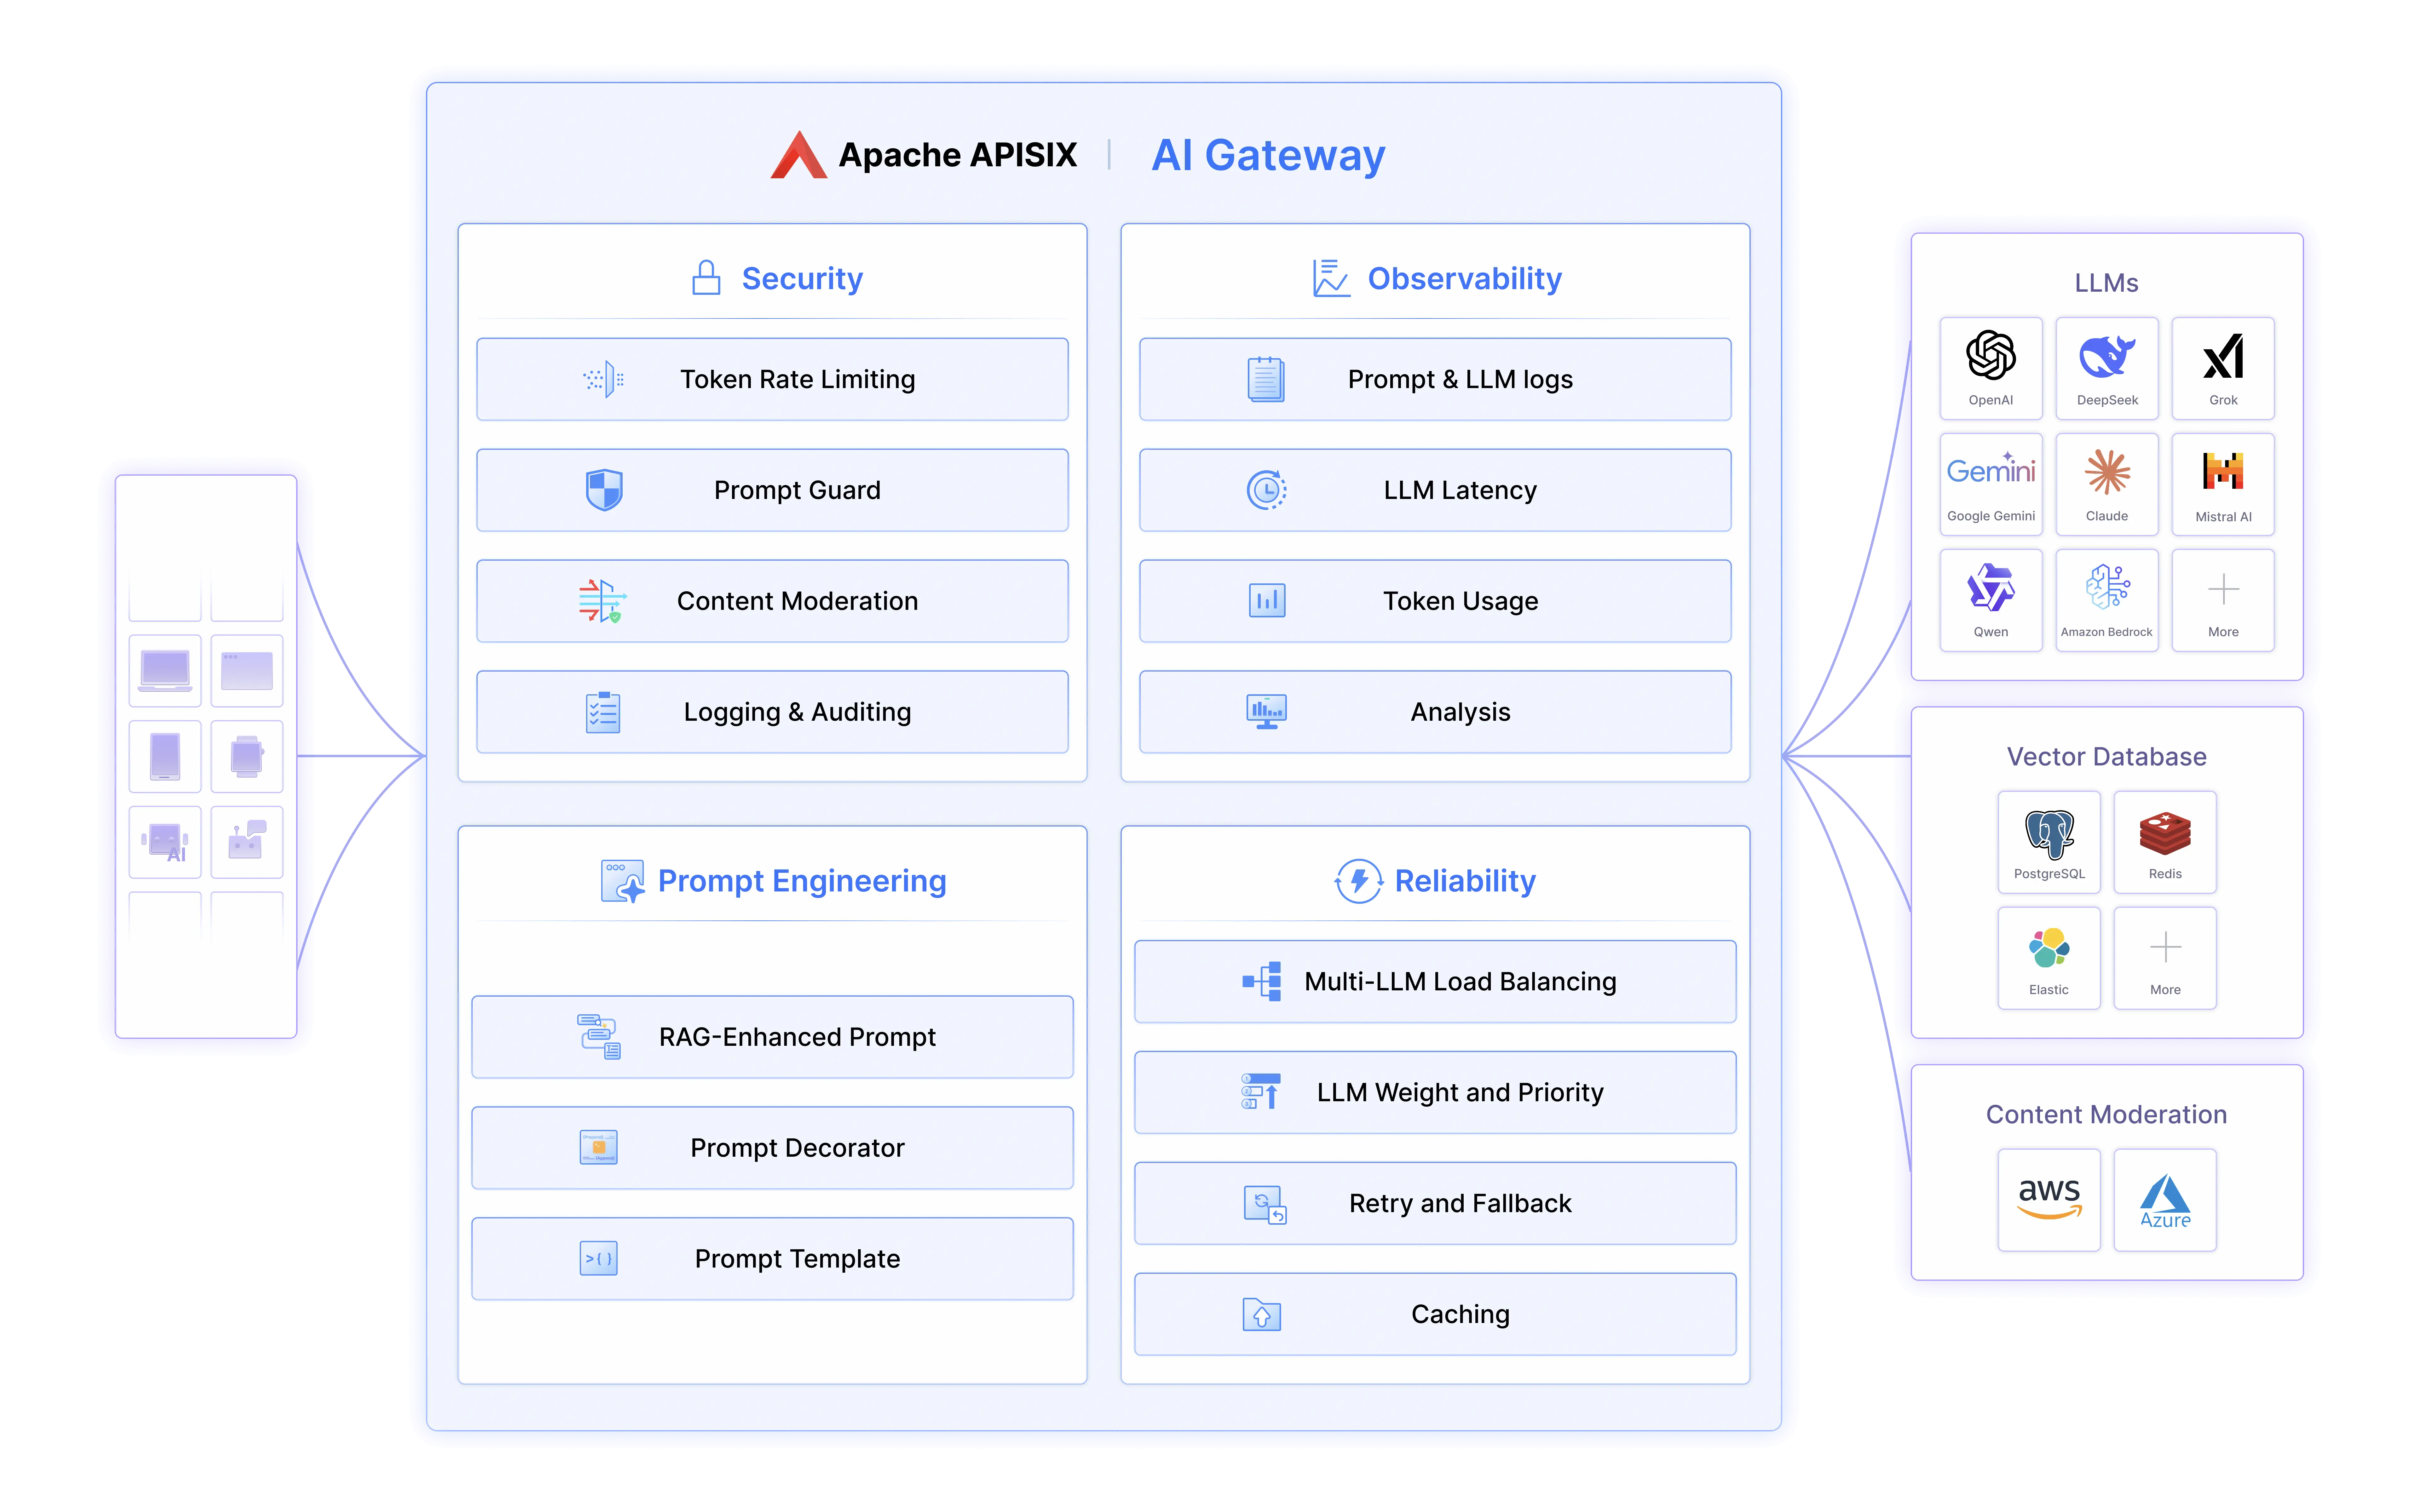
+An AI gateway is a traffic control layer between applications and model providers. It gives teams a shared endpoint for applying provider access, routing, token limits, prompt processing, and telemetry to large language model (LLM) requests. The [Apache APISIX AI Gateway](/ai-gateway/) implements these controls with open-source gateway plugins.
-## Introduction
+## Why AI Traffic Needs Gateway Controls
-In the rapidly evolving landscape of artificial intelligence (AI), Large Language Models (LLMs) and AI agents have become integral to various applications, leading to a surge in AI-related API traffic. As organizations increasingly integrate AI into their workflows, they face new challenges in managing and optimizing AI-driven interactions.
+AI applications often call more than one hosted or self-managed model. They may stream responses, consume usage measured in tokens, and need different routing or retry policies from ordinary web APIs. Without a gateway, each application must implement provider credentials, endpoint selection, limits, and logging independently.
-The advent of open-source LLMs, such as [Deepseek](https://www.deepseek.com/), has enabled enterprises to not only utilize SaaS LLM services from providers like OpenAI and Azure but also to deploy LLMs internally, fostering a hybrid cloud architecture. This shift presents numerous challenges, including data security, multi-LLM adaptation and management, performance optimization, and reliability assurance. Addressing these challenges necessitates the evolution of a traditional API gateway into a specialized [AI gateway](https://apisix.apache.org/blog/2025/02/24/apisix-ai-gateway-features/).
+An AI gateway places these common traffic concerns on the request path between an authorized application and one or more model endpoints. It does not replace the application or the model. Instead, it applies explicitly configured policies before forwarding a request and records information available at the gateway layer.
-
-
-As a PMC member of [Apache APISIX](https://apisix.apache.org/), I have also observed this trend and demand from the open-source community.
-
-## The Rise of LLMs and AI Agents
-
-LLMs and AI agents have transformed how businesses operate, offering enhanced capabilities in natural language understanding, generation, and decision-making. These AI-powered models are now being leveraged in diverse applications, such as:
-
-- **Customer support automation**: AI chatbots and virtual assistants are replacing traditional customer support workflows.
-- **Code generation and software development**: AI-powered tools like GitHub Copilot and DeepSeek assist developers in writing and debugging code.
-- **Financial and legal analysis**: AI models help professionals analyze legal contracts and financial statements.
-- **Content generation**: AI is being used to create marketing content, news articles, and technical documentation.
-
-This transformation has led to an exponential increase in API traffic as applications rely on AI services to process and generate data. The integration of AI into business processes has become a pivotal factor in maintaining a competitive edge, requiring organizations to rethink their API management strategies.
+
-## Emergence of Hybrid Cloud Architectures with Open-Source LLMs
+## Core AI Gateway Capabilities
-The availability of open-source LLMs, such as Deepseek, has empowered organizations to deploy AI models within their own infrastructure. This capability facilitates a hybrid cloud approach, combining public SaaS LLM services with private deployments. While this strategy offers flexibility and control, it also introduces complexities in managing diverse AI environments, ensuring consistent performance, and maintaining security across platforms.
+### Provider Access and Request Transformation
-### Challenges in Managing AI-Driven API Traffic
+Different model providers expose different endpoints, authentication methods, and request formats. A gateway can present a stable application-facing endpoint while adapting requests for supported providers.
-The integration of AI services into applications brings forth several challenges:
+The Apache APISIX [`ai-proxy`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy/) plugin supports documented providers and OpenAI-compatible endpoints. This lets applications send model requests through APISIX without embedding every provider endpoint in application code. Provider support still depends on the plugin configuration and the compatibility of the selected upstream service.
-#### 1. Data Security
+### Multi-Model Routing, Retries, and Fallback
-Transmitting sensitive information to external LLM providers raises concerns about data privacy, regulatory compliance (such as [GDPR](https://gdpr-info.eu/) and [CCPA](https://oag.ca.gov/privacy/ccpa)), and potential data leaks. Organizations must implement robust security measures, such as:
+When an application uses multiple model instances, the gateway can distribute traffic according to a configured policy. The APISIX [`ai-proxy-multi`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy-multi/) plugin supports weighted round robin, consistent hashing, bounded retries, fallback strategies, and optional health checks.
-- Data masking and redaction before sending prompts to external AI services.
-- Role-based access control (RBAC) to limit access to sensitive AI functionalities.
-- Encryption of data in transit and at rest to protect against unauthorized access.
+These controls can reduce the amount of provider-specific failover logic in applications. They do not guarantee uninterrupted service: availability still depends on healthy upstream models, correct retry limits, network conditions, and the chosen fallback policy.
-#### 2. Multi-LLM Adaptation and Management
+
-Different AI tasks require specific LLMs tailored to particular domains, such as coding, user interface design, legal analysis, or financial modeling. Enterprises need to develop strategies to efficiently:
+### Token-Based Usage Limits
-- Route AI requests to the most suitable model based on task requirements.
-- Dynamically switch between different LLM providers based on cost, availability, or latency.
-- Monitor and optimize performance across multiple AI models to ensure consistent quality.
+Request counts alone do not describe LLM usage. A short completion and a long completion can have very different token consumption. Token-aware limits allow teams to place a usage boundary in front of model providers.
-#### 3. Performance and Cost Optimization
+The APISIX [`ai-rate-limiting`](https://apisix.apache.org/docs/apisix/plugins/ai-rate-limiting/) plugin tracks token consumption and can use local or Redis-backed counters. It enforces the limits that operators configure; pricing, budgets, and billing reconciliation remain responsibilities of external systems.
-LLM inference is computationally expensive, leading to significant costs. AI gateway must help optimize resource utilization by:
+### Prompt and Content Processing
-- Caching AI responses to reduce redundant API calls.
-- Implementing token metering to track and control API usage.
-- Load balancing AI requests across multiple providers to optimize response time and cost-efficiency.
+AI gateways can modify or inspect request and response content through separate, purpose-specific controls:
-#### 4. Reliability
+- [`ai-prompt-template`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-template/) applies predefined prompt templates.
+- [`ai-prompt-decorator`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-decorator/) adds configured content before or after a prompt.
+- [`ai-prompt-guard`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-guard/) allows or denies prompts using configured regular-expression patterns.
+- [`ai-aws-content-moderation`](https://apisix.apache.org/docs/apisix/plugins/ai-aws-content-moderation/) and [`ai-aliyun-content-moderation`](https://apisix.apache.org/docs/apisix/plugins/ai-aliyun-content-moderation/) integrate with their documented provider-specific moderation services.
-As AI systems become integral to business operations, ensuring their reliability is paramount. Organizations must implement mechanisms such as:
+These plugins provide specific controls, not a complete security or compliance guarantee. Teams still need application authorization, data classification, secrets management, provider governance, and human review where required.
-- Retry logic and failover strategies to mitigate downtime when an LLM provider experiences service disruptions.
-- Circuit breakers to prevent overloading AI services during peak demand.
-- Latency-based routing to ensure users receive responses from the fastest available LLM instance.
+### Retrieval-Augmented Generation
-## The Role of AI Gateway
+Retrieval-augmented generation (RAG) adds retrieved context to a model request. The APISIX [`ai-rag`](https://apisix.apache.org/docs/apisix/plugins/ai-rag/) plugin documents a flow using Azure OpenAI embeddings and Azure AI Search. It can centralize that supported retrieval step at the gateway, but it does not by itself evaluate factual accuracy or eliminate hallucinations.
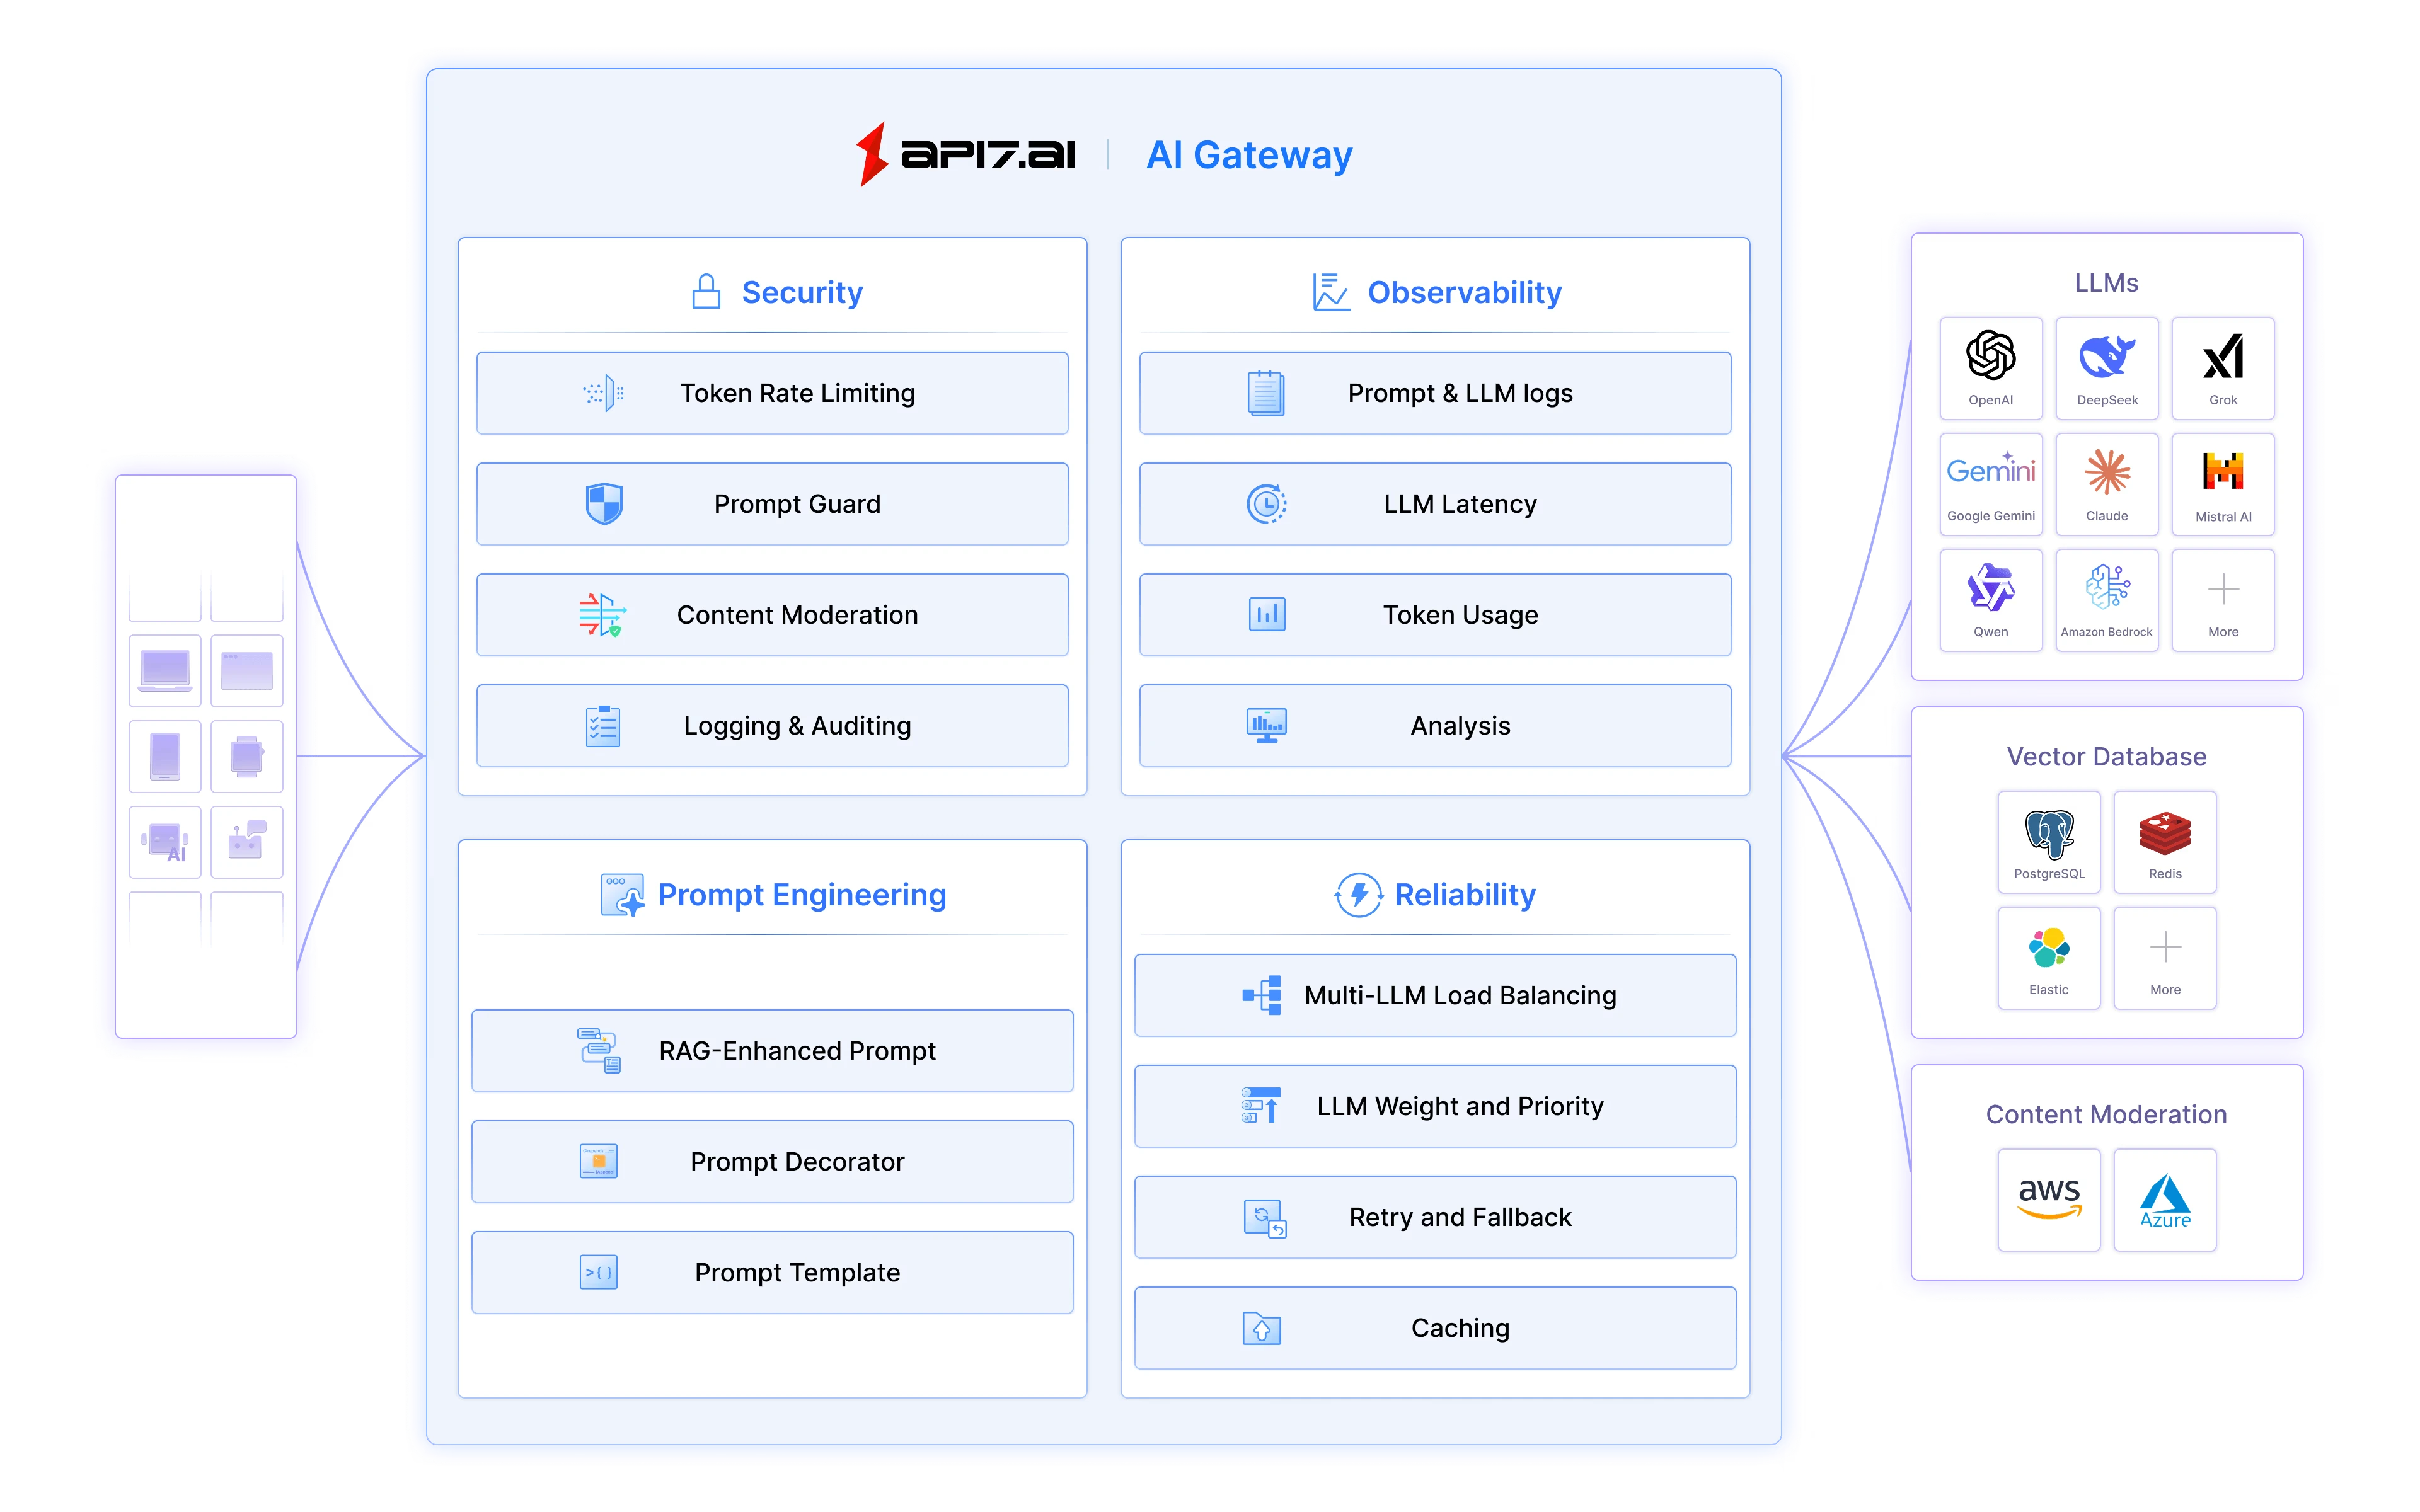
-To address these challenges, the concept of an AI gateway has emerged. An AI gateway extends the functionalities of a traditional API gateway by incorporating features specifically designed for AI applications and LLM scenarios. It serves as a unified endpoint for connecting AI infrastructure and services, providing comprehensive control, security, and observability of AI traffic between applications and models.
+### Gateway-Level Observability
-
+When AI proxy logging is enabled, APISIX can record model, request duration, prompt and response token counts, and time to first token. Existing logging and observability plugins can then export gateway data to the team's monitoring stack.
-### Core Features of an AI Gateway
+Gateway telemetry covers traffic that passes through APISIX. It complements rather than replaces application traces, model-quality evaluation, user feedback, and provider-side monitoring.
-An effective AI gateway encompasses several key functionalities:
+## What an AI Gateway Does Not Own
-#### 1. Security
+The boundary matters because several adjacent responsibilities are often grouped under the term "AI gateway." A gateway can protect and route network traffic, but the surrounding application stack remains responsible for:
-- **Token-Based Rate Limiting**: Controls the rate of requests to AI services, preventing abuse and managing resource utilization.
-- **Prompt Protection**: Ensures that prompts sent to LLMs do not contain sensitive or inappropriate content, safeguarding against unintended data exposure.
-- **Content Moderation**: Monitors and filters responses from AI models to prevent the dissemination of harmful or non-compliant information.
+- authenticating end users and enforcing business-level authorization;
+- selecting tools and deciding when an agent should call them;
+- storing conversation and workflow state;
+- orchestrating multi-step agent behavior;
+- evaluating answer quality, safety, or factual correctness;
+- defining budgets, chargeback rules, and business approvals.
-
+Keeping these responsibilities explicit prevents a gateway policy from being mistaken for an application or model guarantee.
-#### 2. Observability
+## When to Use an AI Gateway
-- **Usage Tracking**: Monitors token consumption and provides insights into how AI services are utilized, aiding in cost management and capacity planning.
-- **Logging and Auditing**: Maintains detailed records of AI interactions, supporting compliance and facilitating troubleshooting.
-- **Real-time Monitoring**: Tracks LLM response times, error rates, and API usage patterns to ensure optimal performance.
+An AI gateway is most useful when several applications share model providers or when teams need consistent traffic controls across AI workloads. Common signals include:
-#### 3. Prompt Engineering
+- provider credentials and endpoints are duplicated across applications;
+- the same token limits or logging rules must be applied to multiple teams;
+- applications need a configured fallback path across model instances;
+- hosted and OpenAI-compatible self-managed endpoints must share one access layer;
+- API and AI traffic should use the same gateway operations and observability stack.
-- **Retrieval-Augmented Generation (RAG)**: Enhances prompts with relevant data to improve the quality and accuracy of AI responses.
-- **Prompt Decorators and Templates**: Standardizes and enriches prompts to ensure consistency and effectiveness across different AI applications.
-- **Dynamic Context Injection**: Automatically enhances user queries with contextual data to improve AI-generated responses.
+A single prototype that calls one provider may not need a dedicated gateway immediately. The value grows as the number of applications, providers, environments, and shared policies increases.
-#### 4. Reliability
+## AI Gateway and API Gateway Relationship
-- **Multi-LLM Load Balancing**: Distributes requests across multiple AI models to optimize performance and prevent overloading.
-
-
+An AI gateway and an API gateway overlap in routing, authentication, rate limiting, resilience, and observability. AI gateways add controls that reflect model traffic, such as token-based limits, model-provider request transformation, prompt processing, and LLM usage summaries.
-- **Retry and Fallback Mechanisms**: Implements strategies to handle AI service failures gracefully, ensuring uninterrupted user experiences.
-- **Traffic Prioritization**: Routes high-priority requests to the most reliable AI services while deferring less critical tasks.
+Apache APISIX uses the same open-source gateway to handle general API traffic and configured AI traffic. Teams can therefore add AI-specific plugins without introducing a separate network layer solely for model calls. For a direct capability comparison, see [AI Gateway vs API Gateway](/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained/).
## Conclusion
-The integration of AI into business operations presents both opportunities and challenges. As AI services are predominantly accessed via APIs, managing these interactions effectively is crucial. AI gateway offers a comprehensive solution by extending traditional API gateway functionalities to meet the specific needs of AI applications. By addressing security, observability, prompt engineering, and reliability, AI gateway enables organizations to harness the full potential of AI while maintaining control and compliance.
+An AI gateway centralizes network-level controls for traffic between applications and model providers. Its practical value is not autonomous decision-making, but consistent provider access, routing, token limits, prompt processing, resilience policies, and gateway telemetry.
-As the AI landscape continues to evolve, the role of AI gateway will become increasingly significant, serving as the backbone of secure and efficient AI deployments. Organizations adopting AI gateway will gain a competitive advantage by ensuring seamless AI interactions, optimizing costs, and maintaining high-performance AI-driven applications.
+Apache APISIX provides these controls through documented open-source plugins while leaving application authorization, agent orchestration, workflow state, and model evaluation in the systems designed to own them.
diff --git a/blog/en/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md b/blog/en/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
index 3efcaa2d0d84b..de5b851c4c05c 100644
--- a/blog/en/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
+++ b/blog/en/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
@@ -1,5 +1,5 @@
---
-title: "What Is an AI Gateway: Differences from API Gateway"
+title: "AI Gateway vs API Gateway: Key Differences and When to Use Each"
authors:
- name: Yilia Lin
title: Technical Writer
@@ -13,143 +13,114 @@ keywords:
- Apache APISIX
- token consumption
- streaming requests
- - AI orchestration
-description: "Compare AI Gateways and traditional API Gateways, including LLM traffic patterns, token controls, model routing, and where Apache APISIX fits."
+ - model routing
+description: "Compare AI gateways and traditional API gateways across traffic patterns, routing, token controls, streaming, security, and operations, and learn when to use each."
image: https://static.api7.ai/uploads/2025/03/21/TIySzjk5_ai-gateway-vs-api-gateway.webp
tags: [Ecosystem]
---
-An AI gateway manages LLM and model traffic, while a traditional API gateway manages general API traffic. This article compares their traffic patterns, controls, and architecture, and explains how the [Apache APISIX AI Gateway](/ai-gateway/) extends an API gateway for AI workloads.
+An API gateway manages general API traffic, while an AI gateway adds controls designed for traffic to large language models (LLMs) and other AI services. The two categories overlap: an AI gateway still needs routing, authentication, rate limiting, resilience, and observability, but it also accounts for model providers, tokens, prompts, and streaming model responses.
-## What Is an AI Gateway? Why Did It Arise in the AI Era?
+## AI Gateway vs API Gateway at a Glance
-The AI era has ushered in unprecedented complexity in deploying and managing artificial intelligence (AI) models. Organizations now juggle multiple models—from computer vision to large language models (LLMs)—across diverse environments (cloud, edge, hybrid). Traditional API gateways, designed for general-purpose data traffic, often fall short in addressing the unique challenges posed by AI workloads. This is where **AI gateways** emerge as critical middleware, acting as a unified control plane for routing, securing, and optimizing AI workloads.
+| Area | API Gateway | AI Gateway |
+| --- | --- | --- |
+| Primary upstreams | Web APIs and microservices | Model providers and AI services |
+| Usage unit | Requests, connections, or bytes | Requests plus prompt and completion tokens |
+| Routing | Host, path, headers, weights, and service health | Those controls plus configured model-instance or provider routing |
+| Request handling | General protocol and payload policies | Provider request transformation and prompt processing |
+| Response patterns | Synchronous, asynchronous, or streaming APIs | Often long-running or streamed model responses |
+| Resilience | Retries, timeouts, circuit breaking, and upstream health checks | Similar controls, with model-provider fallback and token-aware constraints |
+| Observability | Request rate, latency, status, logs, and traces | Gateway metrics plus model, token, and time-to-first-token summaries where supported |
-## The Rise of AI Gateways
+The distinction describes an additional workload and policy set, not necessarily a separate product. Some organizations deploy a purpose-built AI gateway. Others add AI-specific plugins to an API gateway they already operate.
-The proliferation of **generative AI and LLMs (Large Language Models)** has introduced unique challenges:
+## What an API Gateway Does
-- **Token Consumption**: LLMs process requests in tokens, requiring granular tracking for cost and performance optimization.
-- **Stream-Type Requests**: AI agents often generate real-time, streaming responses (e.g., ChatGPT's incremental output), demanding low-latency handling.
-- **Tool Integration**: AI systems increasingly rely on external data sources and APIs (e.g., retrieving live weather data or CRM records).
+An API gateway sits between clients and backend services. It provides a consistent entry point and applies shared traffic policies such as:
-As organizations deploy more LLM-powered applications, token accounting, streaming responses, model routing, and tool access introduce requirements beyond ordinary request routing. An [AI gateway](/blog/2025/03/06/what-is-an-ai-gateway/) centralizes these controls for AI-native traffic.
+- request routing and load balancing;
+- authentication at the gateway edge;
+- rate limiting and traffic shaping;
+- TLS termination and network-level access controls;
+- retries, timeouts, and circuit breaking;
+- gateway logs, metrics, and tracing integrations.
-## AI Agents vs. Traditional Devices: Why Stream-Type Requests Demand Specialized Handling
+These controls reduce duplicated infrastructure logic across APIs. Services still own business authorization, resource-level permissions, domain behavior, and service-specific telemetry.
-AI agents (e.g., chatbots, coding assistants) generate fundamentally different traffic patterns than traditional clients:
+## What an AI Gateway Adds
-| Metric | Traditional API Requests | AI Agent Requests |
-|----------------------|--------------------------|----------------------------|
-| **Request Type** | Synchronous (HTTP GET/POST) | Asynchronous, streaming (SSE) |
-| **Latency** | Milliseconds | Seconds-minutes (for chunks) |
-| **Billing** | Per API call | Per token or compute time |
-| **Failure Modes** | Timeouts, HTTP errors | Partial completions, hallucinations |
+An [AI gateway](/blog/2025/03/06/what-is-an-ai-gateway/) applies gateway controls to model traffic and adds capabilities that reflect how LLM services work.
-### The Stream-Type Challenge
+### Provider Request Transformation
-When an AI agent requests generated content, the response may be streamed incrementally. Gateways handling this traffic need to account for:
+Model providers may use different endpoints, credentials, and request formats. An AI gateway can present a stable application-facing endpoint and transform requests for the providers it supports. Compatibility still depends on the selected provider and gateway implementation.
-- **Partial Responses**: Aggregating chunks into a coherent audit log.
-- **Token Accounting**: Accurately counting tokens across streaming chunks.
-- **Real-Time Observability**: Monitoring latency per token or detecting drift in response quality.
+### Configured Model Routing and Fallback
-AI gateways vary in how they expose tracing and usage metrics. API gateways like [Apache APISIX](https://github.com/apache/apisix) integrate with Prometheus and Grafana, allowing teams to combine established gateway observability with LLM usage data emitted through AI plugins and logs.
+An AI gateway can distribute requests across model instances according to explicit policies such as weights or consistent hashing. Some implementations also provide bounded retries, health checks, or fallback strategies.
-## Two Types of AI Gateways: Purpose-Built vs. API Gateway Evolutions
+This is network traffic management, not autonomous model selection. Deciding which model is best for a task, evaluating response quality, and changing routes based on business outcomes require application logic or a separate evaluation system unless the gateway explicitly provides and is configured for that behavior.
-Today's AI gateways fall into two categories:
+### Token-Aware Limits
-### Specific Purpose-Built AI Gateways
+Traditional rate limits count requests over time. LLM workloads may also need limits based on prompt and completion tokens because requests can vary greatly in size and cost. Token-aware controls can constrain consumption at the gateway, while pricing, budgets, and chargeback remain external concerns.
-These are built from the ground up to address AI use cases. AI-focused platforms and gateways commonly provide capabilities such as:
+### Prompt and Content Controls
-- **Token-Based Rate Limiting**: Enforcing usage quotas based on tokens instead of API calls.
-- **Prompt Engineering Tools**: Allowing developers to test and optimize prompts.
-- **AI-Specific Analytics**: Tracking metrics like response hallucination rates or token costs.
+AI gateways may offer separate functions for prompt templates, prompt decoration, pattern-based prompt checks, content moderation, or retrieval augmentation. Each function has a defined scope. A prompt rule or moderation integration does not replace application authorization, data governance, model evaluation, or compliance review.
-**Example**: LLM providers commonly meter input and output by tokens, so a gateway can use token counters for usage tracking and throttling without depending on a provider's current price.
+### AI Traffic Telemetry
-The available observability, deployment, and policy controls vary by product. Teams should evaluate whether an AI-focused gateway integrates with their existing tracing, logging, and access-control systems.
+Where a provider response exposes the necessary data, an AI gateway can record model names, token usage, request duration, and time to first token. This gateway telemetry complements application traces and provider monitoring; it cannot measure end-user satisfaction, answer correctness, or hallucination rates by itself.
-### Evolved AI Gateways from API Gateways
+## Streaming Does Not Belong Only to AI
-Established API gateway projects such as **[Apache APISIX](https://apisix.apache.org/)** are also adapting to AI workloads by adding:
+LLM applications often use Server-Sent Events (SSE) to return generated text incrementally, but streaming is not unique to AI. Traditional APIs can also use SSE, WebSockets, or other streaming patterns, and some model calls are synchronous.
-- **Streaming Support**: Handling Server-Sent Events (SSE) and WebSockets for real-time AI responses.
-- **Token-Aware Plugins**: Extending rate-limiting plugins to track tokens.
-- **LLM Orchestration**: Managing multiple AI models (e.g., routing requests to cost-effective models like Mistral-7B for simple tasks).
+The practical difference is that model streams may be longer lived and may include usage details only after the response completes. Teams should verify how a gateway handles streaming, timeouts, retries, logging, and partial responses before applying the same policy used for short web requests.
-Mature API gateways bring established security, load-balancing, and usage-control capabilities into the comparison.
+## When to Use an API Gateway
-## Why Teams Extend Existing API Gateways for AI Traffic
+Use an API gateway when the primary requirement is consistent ingress and traffic policy for web APIs or microservices. Typical cases include:
-For teams that already operate an API gateway, extending the existing traffic-management layer can offer three practical benefits:
+- routing requests across backend services;
+- centralizing gateway authentication and rate limits;
+- exposing APIs across Kubernetes, virtual machines, or hybrid environments;
+- applying shared resilience and observability controls.
-1. **Operational Efficiency**: A shared gateway can reduce duplicated policy, deployment, and observability stacks for API and AI traffic.
-2. **Flexibility**: Platforms like Apache APISIX can connect to multiple LLM providers without coupling applications to one model endpoint.
-3. **Consistent Governance**: Existing authentication, traffic control, logging, and security policies can also be applied to AI workloads.
+An API gateway remains useful even if an organization has no LLM workloads.
-## Model Context Protocol (MCP): Bridging AI Assistants and External Tools
+## When to Add AI Gateway Capabilities
-To connect AI applications with external data and tools, the **[Model Context Protocol (MCP)](https://modelcontextprotocol.io/)** defines a client-server protocol for discovering and invoking capabilities, such as:
+Add AI gateway capabilities when model traffic introduces requirements that ordinary request policies do not cover, for example:
-- **Data Sources**: SQL databases, vector stores (e.g., Pinecone).
-- **APIs**: CRM systems, payment gateways.
-- **Tools**: Code interpreters, and image generators.
+- several applications need the same model-provider access layer;
+- teams need token-based limits in addition to request limits;
+- model instances require configured load balancing, retries, or fallback;
+- prompt templates, prompt checks, moderation, or supported RAG processing should run at the gateway;
+- operators need model and token summaries alongside existing gateway telemetry.
-### How MCP Works
+An application that calls one model provider may not need a dedicated AI gateway immediately. The operational value increases with the number of applications, providers, environments, and shared policies.
-1. **Capability Discovery**: An MCP client connects to an MCP server and discovers the tools, resources, or prompts it exposes.
-2. **Tool Invocation**: When an application selects a tool, the client sends a structured request to the MCP server.
-3. **Result Handling**: The MCP server returns the result to the client, and the host application decides how to use it in the model interaction.
+## Using One Gateway for API and AI Traffic
-An API gateway can secure and observe HTTP traffic to remote MCP servers or to APIs used by those servers. Tool selection and response synthesis remain responsibilities of the host application rather than requirements imposed by MCP.
+Apache APISIX is an open-source API gateway that can also apply AI-specific controls through plugins. Its general gateway capabilities handle routing, authentication, resilience, and observability, while AI plugins add provider proxying, configured multi-model routing, token limits, prompt processing, retrieval augmentation, and AI traffic summaries.
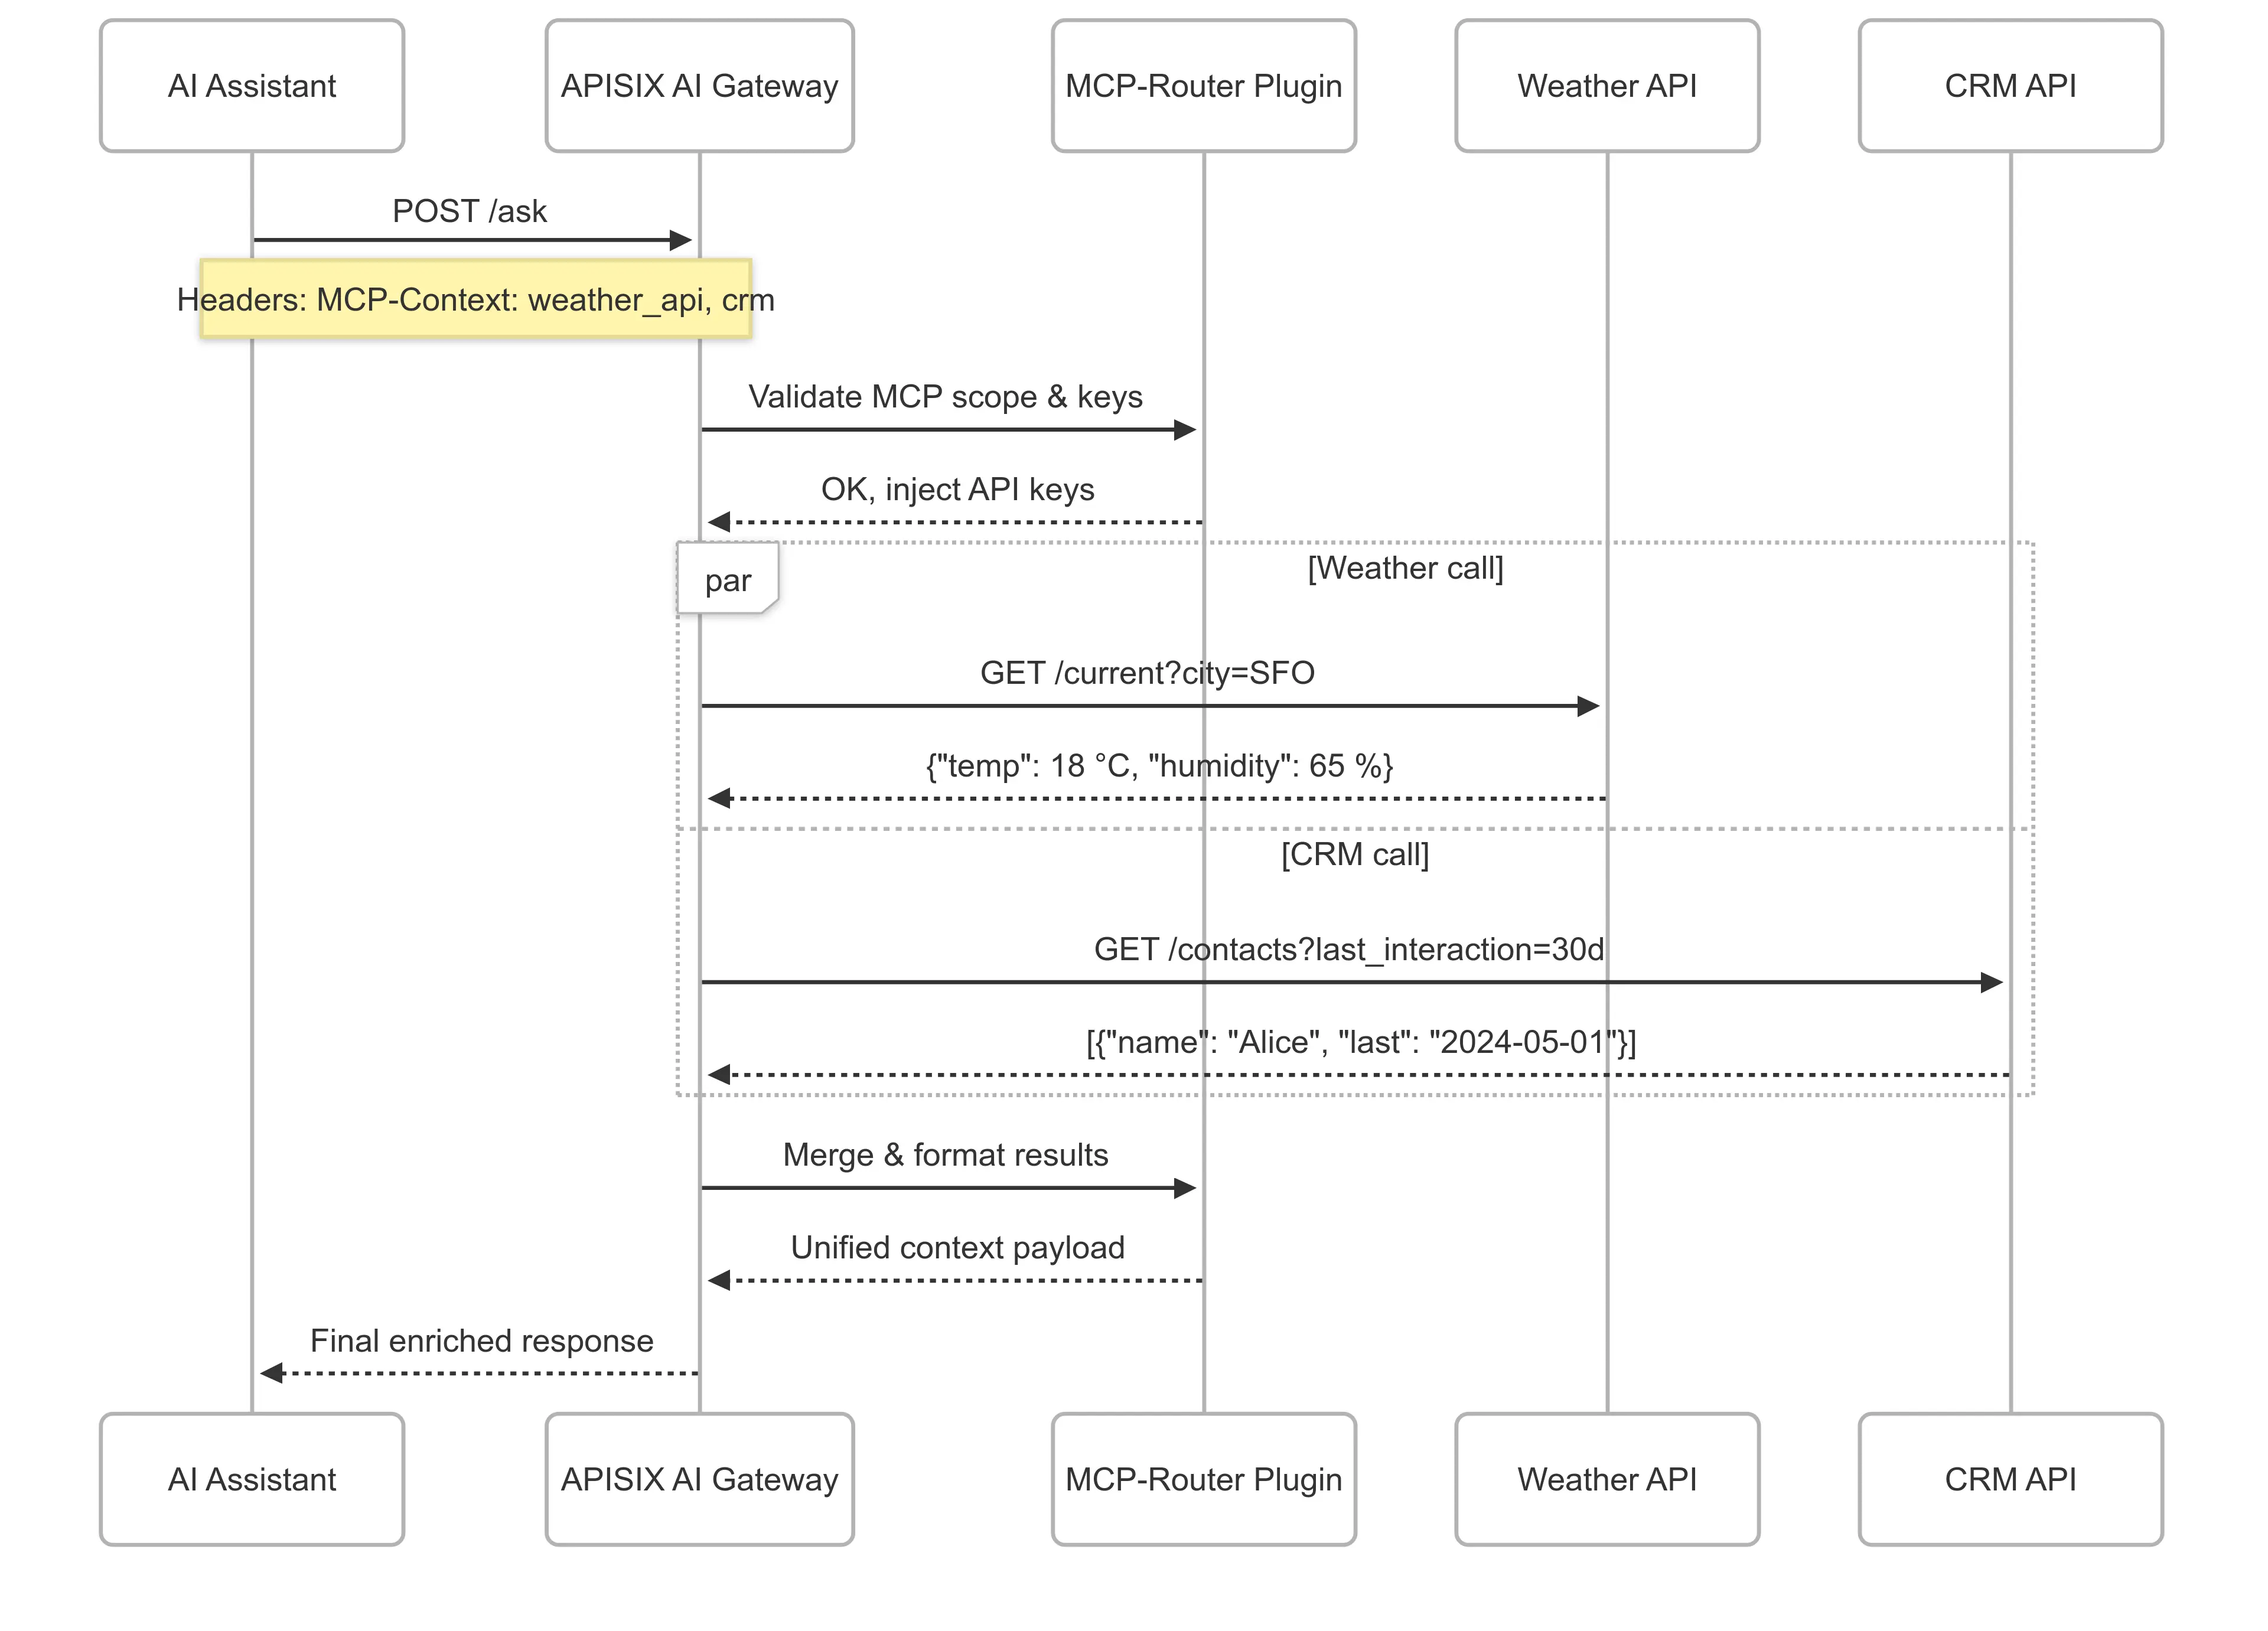
-
+For example:
-**Example**: A user asks, "Email our top client in NYC about today's weather." The host application uses its MCP client to:
+- [`ai-proxy`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy/) connects documented model providers and OpenAI-compatible endpoints.
+- [`ai-proxy-multi`](https://apisix.apache.org/docs/apisix/plugins/ai-proxy-multi/) adds configured load balancing, retries, fallback, and health checks across model instances.
+- [`ai-rate-limiting`](https://apisix.apache.org/docs/apisix/plugins/ai-rate-limiting/) enforces token-based usage limits.
+- [`ai-prompt-guard`](https://apisix.apache.org/docs/apisix/plugins/ai-prompt-guard/) allows or denies prompts using configured patterns.
+- [`ai-rag`](https://apisix.apache.org/docs/apisix/plugins/ai-rag/) provides the retrieval flow documented for Azure OpenAI and Azure AI Search.
-- Discover and call a tool that retrieves the top client from Salesforce.
-- Call a weather tool for the current conditions in NYC.
-- Return the tool results to the host application, which can provide them to the selected model to draft the email.
+This approach lets teams reuse one gateway operations model without describing APISIX as an application runtime or a complete AI governance platform. The [Apache APISIX AI Gateway overview](/ai-gateway/) maps each workload requirement to its corresponding plugin.
-### MCP and API Gateway Responsibilities
+## Conclusion
-- **Interoperability**: MCP standardizes how host applications communicate with servers that expose tools and resources.
-- **Gateway Security**: API gateway policies can protect and observe HTTP services used by an MCP deployment.
-- **Application Orchestration**: The host application remains responsible for choosing tools, combining results, and managing the model interaction.
+API gateways and AI gateways solve overlapping traffic-management problems. An API gateway provides the general foundation for APIs and microservices. An AI gateway adds provider, token, prompt, retrieval, and model-telemetry controls for AI workloads.
-## Future of AI Gateways: Convergence with API Management
-
-As AI adoption matures, two trends will shape AI gateways:
-
-### Trend 1: Convergence Between AI and API Gateways
-
-AI-focused and general-purpose gateways increasingly overlap in the capabilities they offer:
-
-- **Unified Governance**: One platform for REST, GraphQL, and AI APIs.
-- **Usage Controls**: Token-aware limits and metering signals for external billing systems.
-- **Enterprise Features**: Role-based access control (RBAC), audit logging.
-
-The appropriate architecture depends on whether a team needs a dedicated AI control plane, an extension of its existing gateway, or both.
-
-### Trend 2: More AI-Aware Traffic Controls
-
-AI gateways and AI-aware API gateways are adding controls for:
-
-- **Model Routing**: Directing requests to optimal models based on cost, latency, or accuracy.
-- **Hybrid Workflows**: Blending AI and non-AI services (e.g., validating a model response against a database).
-- **Token Analytics**: Real-time dashboards showing token spend by team or project.
-
-### The Bottom Line
-
-The line between "AI gateway" and "API gateway" is becoming less rigid as both product categories add model routing, token controls, security, and observability. Teams can evaluate these capabilities against their requirements for scale, cost control, security, and operational consistency.
-
-## Conclusion: Embracing AI-API Convergence
-
-AI gateways and API gateways address overlapping but distinct concerns. Purpose-built products may offer specialized model tooling, while established API gateways can extend existing routing, security, and observability controls to AI traffic.
-
-Solutions like **[Apache APISIX AI Gateway](/blog/2025/02/24/apisix-ai-gateway-features/)** combine AI-specific traffic controls with general API management. The right approach depends on a team's model providers, existing infrastructure, governance requirements, and operational preferences.
+Choose based on the policies the workload needs. Teams can deploy separate gateways when organizational or technical boundaries require it, or use a gateway such as Apache APISIX to manage general API and configured AI traffic through one open-source platform.
diff --git a/blog/en/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md b/blog/en/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
index 053af52cb7384..c3f74f0845313 100644
--- a/blog/en/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
+++ b/blog/en/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
@@ -84,5 +84,5 @@ AI agents are becoming a primary interface for infrastructure. Teaching them to
## Further reading
-- [Apache APISIX AI Gateway](https://apisix.apache.org/ai-gateway/) — LLM proxying, load balancing, token-based rate limiting, and MCP support
+- [Apache APISIX AI Gateway](https://apisix.apache.org/ai-gateway/) - LLM proxying, load balancing, token-based rate limiting, prompt controls, and gateway-level observability
- [AI Agent Skills for Apache APISIX](https://docs.api7.ai/apisix/ai-agent-skills) — the full, searchable skills catalog
diff --git a/blog/zh/blog/2025/02/24/apisix-ai-gateway-features.md b/blog/zh/blog/2025/02/24/apisix-ai-gateway-features.md
index 8805836a33330..181ee851c0e7c 100644
--- a/blog/zh/blog/2025/02/24/apisix-ai-gateway-features.md
+++ b/blog/zh/blog/2025/02/24/apisix-ai-gateway-features.md
@@ -1,135 +1,95 @@
---
-title: "APISIX 的 AI Gateway 功能一览:LLM 代理、Token 限流、安全防护"
+title: "Apache APISIX AI 网关核心功能"
keywords:
- APISIX
- - AI Gateway
- - LLM Proxy
- - API Gateway for AI
- - Token Rate Limiting
- - AI Security
- - AI Traffic Management
- - Open-Source API Gateway
- - Multi-LLM Load Balancing
- - AI API Protection
- - AI Request Throttling
-description: 探索 APISIX AI Gateway 的强大功能,包括 LLM 代理、智能流量调度、Token 限流、安全防护等。通过开源插件实现多 LLM 负载均衡、API 速率控制、内容审核,优化 AI 应用的性能、安全性和成本控制。
+ - AI 网关
+ - LLM API
+ - Token 限流
+ - 模型路由
+ - 多 LLM 代理
+ - 提示词控制
+ - AI 响应缓存
+ - 语义路由
+ - AI 可观测性
+description: "了解 Apache APISIX AI 网关如何通过模型代理、配置型路由、响应缓存、Token 限制、提示词控制、RAG 和可观测性管理 LLM 流量。"
tags: [Ecosystem]
---
-> 本文将详细介绍当前及未来几个版本 APISIX 的 AI 网关功能。作为一个多功能的 API 和 AI 网关,Apache APISIX 将为 AI 应用提供了高效且安全的 LLM API 调用。
+[Apache APISIX AI 网关](/zh/ai-gateway/)通过开源插件为 LLM 流量提供模型代理、配置型路由、响应缓存、Token 限制、提示词控制、检索和网关层可观测能力。本文将这些能力与对应的 APISIX 插件逐一关联。
-## 引言:AI 代理的崛起与 AI Gateway 的演进
+## 为什么 AI 流量需要额外的网关控制
-近年来,AI 代理发展迅猛,如 AutoGPT、Chatbots、AI Assistants 等应用不断涌现。它们依赖于大语言模型(LLM)的 API 调用,而高并发、成本控制、安全等挑战也随之而来。
+LLM 请求与普通 API 流量一样,需要身份认证、路由、限流、故障处理和可观测性。同时,它还涉及供应商特定的请求格式、按 Token 计算的用量、持续时间较长的流式响应,以及提示词处理等要求。
-传统的 API 网关主要服务于 Web API 和微服务,并未针对 AI 应用的特殊需求进行优化,因此催生了 AI Gateway 的概念。AI Gateway 需要在以下几个方面提供增强能力:
+Apache APISIX 在已授权应用和已配置模型端点之间的网络路径上处理这些问题。它不负责选择工具、编排 Agent 工作流、评估回答质量,也不能替代应用层授权。这些职责仍属于应用和 AI 平台层。
-- **多 LLM 代理**:支持多个 LLM 供应商,避免供应商锁定
-- **Token 速率限制**:防止 API 滥用,优化成本管理
-- **安全防护**:包括提示词过滤、内容审核等,确保 AI 应用的合规性
-- **智能流量管理**:根据成本、延迟、稳定性,动态调整 LLM 权重
+## 代理到受支持的模型供应商
-Apache APISIX 不仅是 API 网关,也通过插件成为了 AI 网关,帮助 AI 应用更高效、安全地调用 LLM API。
+[`ai-proxy`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy/) 插件可将请求转发到文档列出的模型供应商和 OpenAI 兼容端点。它可以转换受支持的请求格式、从网关配置中附加供应商凭证,并向应用提供一致的访问端点。
-## LLM Proxy:高效管理多个 LLM 后端
+实际兼容性取决于所选的 APISIX provider 类型和上游 API。团队应核对每个供应商的请求和响应字段,而不应假设所有模型都实现相同接口。
-AI 应用通常不会只依赖一个 LLM 供应商,而是需要根据需求动态选择最佳模型。例如:
+## 配置多模型路由与故障处理
-- 使用 OpenAI GPT-4 进行通用文本生成,使用 Claude 进行法律文档处理
-- 在 Mistral 和 Gemini 之间切换,以优化成本和吞吐量
+[`ai-proxy-multi`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy-multi/) 插件在已配置的模型实例之间分配请求。其文档列出的策略包括加权轮询和一致性哈希,并可配置健康检查、有限重试和 fallback 行为。
-**Apache APISIX 的 LLM Proxy 提供以下能力:**
+APISIX 3.18 还支持语义路由算法。运维人员为每个实例提供示例提示词并配置 embedding 服务;插件会比较请求提示词与这些示例的相似度,选择达到阈值且最相近的实例。这是显式配置的意图路由,不是基于模型成本、延迟、回答质量或业务结果的自动优化。
-✅ 支持多个 LLM 供应商(OpenAI, DeepSeek, Claude, Mistral, Gemini, etc.),避免供应商锁定
+语义路由不参与健康检查、重试或常规 fallback 策略。只有在没有实例达到相似度阈值或 embedding 请求失败时,才会使用其指定的 fallback。加权轮询和一致性哈希仍使用各自文档所述的故障处理选项。
-✅ LLM 权重和优先级管理,基于业务需求调整流量分配
+
-✅ 智能负载均衡,依据延迟、成本、稳定性 动态调整 LLM 权重
+这些能力可以减少应用中的供应商特定路由逻辑,但不能保证服务永不中断。可用性仍取决于上游健康状态、网络条件、超时、重试上限和配置的 fallback 路径。
-✅ 重试与备用机制,确保某个 LLM API 发生故障时业务不中断
+## 执行基于 Token 的用量限制
-✅ 支持同一 LLM 不同供应商之间的负载均衡,例如:
+不同 LLM 请求消耗的输入和输出 Token 数量可能相差很大。[`ai-rate-limiting`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rate-limiting/) 插件可根据 Token 消耗而不只是请求次数执行限流。
-- 私有部署的 DeepSeek
-- 官方 DeepSeek API
-- 火山引擎的 DeepSeek API
+该插件支持本地和 Redis 计数器。运维人员可以通过网关配置设定适合应用的用量边界。插件会在收到响应后记录提供商返回的用量,并在观察到的计数已耗尽额度后拒绝后续请求。因此,单个大响应或并发请求仍可能使观察到的用量超过配置限制,之后的请求才会被拒绝。模型定价、预算、账单核对和成本分摊仍需由外部系统负责。
-用户可以根据延迟、稳定性、价格等因素,灵活分配不同 DeepSeek 供应商的流量权重,实现最佳调用策略。
+## 缓存完整的 LLM 响应
-这些能力让 AI 应用能够灵活适配不同的 LLM,提高可靠性,降低 API 调用成本。
+[`ai-cache`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-cache/) 插件与 `ai-proxy` 或 `ai-proxy-multi` 配合,将完整的 LLM 响应缓存到 Redis。精确匹配默认启用。团队也可以选择增加语义匹配,这要求 Redis 部署提供所需的 Redis Search 命令,并配置 embedding 服务。[Redis 集成指南](https://apisix.apache.org/zh/integrations/redis/) 的配套实验固定使用 Redis Open Source 8.10.1;若使用更早的 Redis Open Source 或 Redis Stack 版本,应固定并明确测试具体版本。
-## AI 安全防护:确保 AI 使用安全与合规
+对于流式响应,插件只有在收到终止事件后才会写入缓存;中断的流不会被缓存,因此不会回放不完整响应。团队仍需根据应用的数据和时效要求配置缓存资格、隔离范围、过期时间、绕过规则和语义阈值。
-AI API 可能会涉及敏感数据和误导性信息,甚至可能被滥用。因此,AI 网关需要在多个层面提供安全保障。
+缓存条目默认按 Route 隔离,而不是按 Consumer 隔离。在多租户 Route 上,应先认证每个租户,再启用 `cache_key.include_consumer`,按 Consumer 身份划分缓存。如果租户身份来自其他可信服务端来源,可通过 `cache_key.include_vars` 加入对应的 NGINX 变量。未经认证的流量仍会共享 Route 级缓存,除非加入可信服务端变量;仅由客户端控制的请求头不能作为租户隔离边界。
-**Apache APISIX 提供的 AI 安全能力包括:**
+## 使用职责明确的提示词与内容控制
-✅ AI RAG(Retrieval-Augmented Generation),支持企业自有知识库,降低 LLM 幻觉,提高输出可靠性
+APISIX 为不同的提示词处理需求提供了独立插件:
-✅ 提示词防护,自动拦截敏感、违法、不适当的提示词,防止用户恶意使用
+- [`ai-prompt-template`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-template/) 应用预定义的提示词模板。
+- [`ai-prompt-decorator`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-decorator/) 在提示词前后添加配置内容。
+- [`ai-prompt-guard`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-guard/) 根据配置的正则表达式允许或拒绝提示词。
+- [`ai-aws-content-moderation`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-aws-content-moderation/) 按文档所述流程集成 Amazon Comprehend。
+- [`ai-aliyun-content-moderation`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-aliyun-content-moderation/) 按文档所述流程集成阿里云内容审核服务。
+- [`ai-lakera-guard`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-lakera-guard/) 集成 Lakera Guard v2 API,与 `ai-proxy` 或 `ai-proxy-multi` 配合后,可按配置检查受支持的 LLM 请求、响应或两者。
-✅ 提示词装饰器,自动在用户的输入前后添加内容,增强 LLM 生成质量
+这些控制具有不同的范围和失败处理方式。模式匹配和供应商特定的内容审核无法保证内容绝对安全或符合所有合规要求。团队仍需实施应用授权、数据分类、密钥管理、供应商治理,并在必要时安排人工审核。
-✅ 提示词模版,让用户更方便地复用标准化提示词,提升交互体验
+## 添加文档支持的 RAG 检索步骤
-✅ 返回内容审核,拦截敏感或违规 的 AI 生成内容
+[`ai-rag`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rag/) 插件实现了当前文档中基于 Azure OpenAI Embeddings 和 Azure AI Search 的检索流程。它会检索相关上下文,并将其加入受支持的模型请求。
-✅ 日志与审计,提供完整 API 请求日志,便于合规审计
+该能力可以为兼容部署集中处理文档所述的检索步骤,但它不是适用于所有知识库的通用连接器,也不能评估事实准确性或消除模型幻觉。
-这些安全措施确保 AI 应用符合企业级安全要求,避免因 AI 误导性内容导致合规风险。
+## 在网关层观察 AI 流量
-## Token 可观测性与管理:防止 API 滥用导致高额账单
+启用 AI 代理日志后,如果上游响应提供相应信息,APISIX 可以记录模型、请求耗时、输入和输出 Token 数量,以及首个 Token 返回时间。现有日志和可观测性插件可以将这些网关数据导出到团队的监控系统。
-调用 LLM API 需要消耗 Token,滥用 API 可能导致巨额成本。Apache APISIX 提供精细化的 Token 监控和管理机制。
+网关遥测只覆盖经过 APISIX 的请求。它补充而非替代应用链路追踪、供应商侧监控、用户反馈和模型质量评估。
-**Apache APISIX 的 Token 管理能力:**
+## 使用同一网关管理 API 与 AI 流量
-✅ 按 Route/Service/Consumer/Consumer Group/自定义维度进行 Token 限流限速
+Apache APISIX 可以将现有的路由、身份认证、流量管理和可观测能力与 AI 专用插件结合使用。当这种架构符合团队需求时,可以通过同一个开源网关管理 API 和已配置的模型流量。
-✅ 支持多种限流模式:
+其价值来自明确且可审查的策略,而不是自动决策。团队需要配置 APISIX 使用的供应商、路由、缓存策略、限制、提示词控制、检索服务和可观测性集成。
-- 单机 vs. 集群限流,适应不同规模的 AI API 服务
-- 固定时间窗口 vs. 滑动时间窗口,灵活控制 API 速率
+## 总结
-✅ 对不同 LLM 设置不同的限流策略,避免成本失控
+Apache APISIX 通过职责明确的插件增加 AI 流量控制,包括供应商代理、配置型多模型与语义路由、响应缓存、有限重试与 fallback、Token 限制、提示词处理、外部内容审核集成、文档支持的 Azure RAG 流程和网关层遥测。
-通过 Apache APISIX,企业可以实现 Token 资源的精细化管理,防止 API 滥用带来的高额账单。
-
-## 智能路由:AI API 的动态流量管理
-
-在 AI API 调用过程中,不同的任务可能需要不同的 LLM。例如:
-
-- 代码生成请求 → 发送至 GPT-4 或 DeepSeek
-- 长篇摘要任务 → 发送至 Claude
-- 普通对话 → 发送至 GPT-3.5 或 Gemini
-
-**Apache APISIX 的智能路由能力:**
-
-✅ 基于请求内容的智能路由(Context-Aware Routing)
-
-- 根据提示词(Prompt)类型 选择最优 LLM
-- 按用户级别(付费用户 vs. 免费用户) 分配不同的模型(GPT-4 Turbo vs. GPT-3.5)
-
-✅ 缓存优化(Response Caching),减少重复 API 调用,提升响应速度
-
-这些能力帮助 AI API 运行更加高效,降低 API 延迟,提高吞吐量。
-
-## 结语
-
-随着 AI 技术的快速发展,API Gateway 也需要不断进化,适应 AI 应用的特殊需求。Apache APISIX 通过 LLM Proxy、Token 速率限制、安全防护和智能路由等功能,成为 AI Gateway 的最佳选择。
-
-**Apache APISIX 相较于传统 API Gateway 的核心优势**
-
-🚀 支持多 LLM 供应商,避免供应商锁定
-
-⚡️ 智能流量调度,动态负载均衡,提高 API 可靠性
-
-🔒 内置安全能力,包括提示词防护、内容审核,确保 AI API 安全合规
-
-💰 Token 限流限速,避免 API 滥用导致高额账单
-
-📊 高性能架构,满足 AI 应用的高并发需求
-
-如果你正在构建 AI 相关应用,并希望同时拥有强大的 API Gateway 和 AI Gateway,不妨试试 Apache APISIX!🎯
+这些能力应在各自的文档边界内使用。APISIX 管理到模型服务的流量;业务授权、Agent 编排、工作流状态、模型评估和合规决策仍由外围应用系统负责。
diff --git a/blog/zh/blog/2025/03/06/what-is-an-ai-gateway.md b/blog/zh/blog/2025/03/06/what-is-an-ai-gateway.md
index a37f15a852573..67e27c2ae3164 100644
--- a/blog/zh/blog/2025/03/06/what-is-an-ai-gateway.md
+++ b/blog/zh/blog/2025/03/06/what-is-an-ai-gateway.md
@@ -12,123 +12,104 @@ authors:
keywords:
- AI 网关
- API 网关
- - LLM 负载均衡
- - AI 安全性
+ - 大语言模型
- 多 LLM 管理
+ - 模型路由
+ - Token 限流
- AI 可观测性
- - AI 提示词工程
- - AI 可靠性
-description: 本文探讨 AI 网关如何应对 API 网关领域的关键挑战,揭示其如何释放人工智能的全部潜能,将技术瓶颈转化为发展机遇。
+description: "了解什么是 AI 网关,以及 Apache APISIX 如何管理 LLM API 流量、模型路由、Token 限制、提示词控制和可观测性。"
tags: [Ecosystem]
+image: https://static.api7.ai/uploads/2025/03/07/1W9olFmu_what-is-ai-gateway.webp
---
-> 本文探讨 AI 网关如何应对 API 网关领域的关键挑战,揭示其如何释放人工智能的全部潜能,将技术瓶颈转化为发展机遇。
+AI 网关是位于应用和模型供应商之间的流量控制层。它为大语言模型(LLM)请求提供统一入口,用于实施供应商访问、路由、Token 限制、提示词处理和遥测策略。[Apache APISIX AI 网关](/zh/ai-gateway/)通过开源网关插件实现这些控制。
-## 引言
+## 为什么 AI 流量需要网关控制
-在人工智能技术快速演进的时代背景下,大型语言模型(LLMs)和 AI 智能体已成为各类应用的核心组件,引发 AI 相关 API 流量的指数级增长。随着企业将 AI 深度整合至业务流程,如何有效管理和优化 AI 驱动的交互正成为新的技术挑战。
+AI 应用经常需要调用多个托管或自建模型。它们可能返回流式响应、按 Token 计算用量,并且需要不同于普通 Web API 的路由或重试策略。如果没有网关,每个应用都需要分别实现供应商凭证、端点选择、用量限制和日志记录。
-以[深度求索(Deepseek)](https://www.deepseek.com/)为代表的开源 LLM 技术兴起,使得企业不仅能够使用 OpenAI、Azure 等 SaaS 化 LLM 服务,更可在私有化环境中部署 LLM 模型,形成混合云架构。这一技术范式迁移带来了数据安全、多 LLM 适配管理、性能优化和可靠性保障等系列挑战,传统 API 网关向专业化 [AI 网关](https://apisix.apache.org/zh/blog/2025/02/24/apisix-ai-gateway-features/)的演进势在必行。
+AI 网关位于已授权应用和一个或多个模型端点之间,将这些通用流量问题放在统一的请求路径上处理。它不会取代应用或模型,而是根据明确配置的策略转发请求,并记录网关层能够获取的信息。
-
+
-作为 [Apache APISIX](https://apisix.apache.org/zh/) 项目的 PMC 成员,我在开源社区也深切感知到这一技术趋势和市场需求。
+## AI 网关的核心能力
-## LLM 和 AI 代理的崛起
+### 供应商访问与请求转换
-LLM 和 AI 智能体通过增强自然语言理解、生成和决策能力,正在重塑企业运营模式。典型应用场景包括:
+不同模型供应商使用不同的端点、身份认证方式和请求格式。网关可以为应用提供稳定入口,并为受支持的供应商转换请求。
-- **智能客服自动化**:AI 聊天机器人和虚拟助手正在替代传统客服流程
-- **代码生成与软件开发**:GitHub Copilot、DeepSeek 等 AI 工具辅助开发者编程和调试
-- **金融法律分析**:AI 模型协助专业人士解析法律合同与财务报表
-- **内容生成引擎**:AI 驱动的营销文案、新闻稿件和技术文档自动生成
+Apache APISIX 的 [`ai-proxy`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy/) 插件支持文档列出的供应商和 OpenAI 兼容端点。应用可以通过 APISIX 发送模型请求,无需在应用代码中直接写入每个供应商的端点。实际兼容性仍取决于插件配置和所选上游服务。
-这场技术变革导致应用系统对 AI 服务的调用量呈爆发式增长。AI 与业务流程的深度集成已成为企业保持竞争优势的关键要素,这要求技术团队必须重构原有的 API 管理策略。
+### 多模型路由、重试与 Fallback
-## 开源 LLM 驱动的混合云架构兴起
+当应用使用多个模型实例时,网关可以按照配置策略分配流量。[`ai-proxy-multi`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy-multi/) 插件支持加权轮询、一致性哈希、有限重试、fallback 策略和可选健康检查。
-以 Deepseek 为代表的开源 LLM 技术,使企业能够在自有基础设施中部署 AI 模型。这种能力催生了混合云架构的普及,即公有云 SaaS 化 LLM 服务与私有化部署相结合的技术方案。这种架构虽提供了灵活性和可控性,但也带来了混合环境管理、跨平台性能一致性保障和安全体系构建等复杂度提升的技术挑战。
+这些控制可以减少应用中的供应商特定故障处理逻辑,但不能保证服务永不中断。可用性仍取决于健康的上游模型、合理的重试上限、网络条件和选定的 fallback 策略。
-### AI 驱动型 API 流量管理痛点
+
-AI 服务与业务系统深度集成主要面临以下技术挑战:
+### 基于 Token 的用量限制
-#### 1. 数据安全治理
+仅统计请求数无法准确描述 LLM 用量。短响应和长响应消耗的 Token 数量可能相差很大。Token 感知的限制可以在模型供应商前设置用量边界。
-将敏感信息传输到外部 LLM 提供商引发了关于数据隐私、法规合规性(如 [GDPR](https://gdpr-info.eu/) 和 [CCPA](https://oag.ca.gov/privacy/ccpa))以及潜在数据泄露的担忧。企业必须实施强大的安全措施,例如:
+[`ai-rate-limiting`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rate-limiting/) 插件跟踪 Token 消耗,并支持本地或 Redis 计数器。它执行运维人员配置的限制;定价、预算和账单核对仍由外部系统负责。
-- **数据泄露防控**:在将提示词发送到外部 AI 服务之前进行数据屏蔽和删减。
-- **访问控制体系**:基于角色的访问控制(RBAC),以限制对敏感 AI 功能的访问。
-- **数据加密**:对传输中和静态数据进行加密,以防止未授权访问。
+### 提示词与内容处理
-#### 2. 多模型适配与管理
+AI 网关可以通过职责不同的控制修改或检查请求与响应内容:
-不同的 AI 任务需要特定于特定领域的 LLM,如代码生成、UI设计、法律分析、金融建模。企业需建立:
+- [`ai-prompt-template`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-template/) 应用预定义的提示词模板。
+- [`ai-prompt-decorator`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-decorator/) 在提示词前后添加配置内容。
+- [`ai-prompt-guard`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-guard/) 根据配置的正则表达式允许或拒绝提示词。
+- [`ai-aws-content-moderation`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-aws-content-moderation/) 和 [`ai-aliyun-content-moderation`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-aliyun-content-moderation/) 分别集成其文档所述的供应商审核服务。
-- **智能路由机制**:根据任务特征动态为 AI 请求选择最优模型
-- **供应商切换能力**:基于成本、可用性和延迟指标进行服务商动态切换
-- **多模型监控体系**:实现跨模型性能监控与质量一致性保障
+这些插件提供具体控制,而不是完整的安全或合规保证。团队仍需实施应用授权、数据分类、密钥管理、供应商治理,并在需要时安排人工审核。
-#### 3. 性能和成本优化
+### 检索增强生成
-LLM 推理的高算力消耗带来显著成本压力,AI 网关需通过以下技术手段实现资源优化:
+检索增强生成(RAG)会把检索到的上下文添加到模型请求中。[`ai-rag`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rag/) 插件记录了使用 Azure OpenAI Embeddings 和 Azure AI Search 的流程。它可以在网关集中执行受支持的检索步骤,但不能单独评估事实准确性或消除模型幻觉。
-• **响应缓存机制**:通过 AI 结果缓存减少重复 API 调用
-• **令牌计量体系**:精准跟踪和控制 API 使用量
-• **负载均衡策略**:跨供应商的智能流量调度以平衡响应速度与成本
+### 网关层可观测性
-#### 4. 服务可靠性保障
+启用 AI 代理日志后,如果上游响应提供相应信息,APISIX 可以记录模型、请求耗时、输入和输出 Token 数量,以及首个 Token 返回时间。现有日志和可观测性插件可以将网关数据导出到团队的监控系统。
-当 AI 系统成为业务核心组件时,高可用架构设计需包含:
+网关遥测只覆盖经过 APISIX 的流量。它补充而非替代应用链路追踪、模型质量评估、用户反馈和供应商侧监控。
-- **容错重试机制**:在 LLM 服务异常时自动切换备用节点,减少因服务中断导致的停机时间
-- **熔断保护策略**:流量洪峰时实施服务熔断,防止在高峰需求期间 AI 服务过载
-- **智能路由优化**:基于实时延迟指标选择最优 LLM 实例节点
+## AI 网关不负责什么
-## AI 网关的作用
+明确边界很重要,因为一些相邻职责经常被笼统归入 “AI 网关”。网关可以保护和路由网络流量,但外围应用系统仍负责:
-为应对上述挑战,AI 网关应运而生。AI 网关通过纳入专为 AI 应用和 LLM 场景设计的功能,扩展了传统 API 网关的功能。它作为连接 AI 基础设施和服务的统一端点,提供对应用程序和模型之间 AI 流量的全面控制、安全性和可观测性。
+- 认证最终用户并执行业务级授权;
+- 选择工具并决定 Agent 何时调用工具;
+- 保存对话和工作流状态;
+- 编排多步骤 Agent 行为;
+- 评估回答质量、安全性和事实准确性;
+- 定义预算、成本分摊规则和业务审批。
-
+明确这些职责可以避免把网关策略误解为应用或模型保证。
-成熟的 AI 网关应具备以下关键能力:
+## 什么时候需要 AI 网关
-### 1. 安全
+当多个应用共享模型供应商,或团队需要在 AI 工作负载之间实施一致流量控制时,AI 网关最有价值。常见信号包括:
-- **基于令牌的速率限制**:基于 Token 实现 API 调用频次管控,防止资源滥用
-- **提示词安全过滤**:对输入提示词进行敏感内容检测,防范数据泄露风险
-- **内容审核**:实时监测 AI 输出内容,拦截违法违规信息
+- 供应商凭证和端点在多个应用中重复配置;
+- 多个团队需要相同的 Token 限制或日志规则;
+- 应用需要在模型实例之间配置 fallback 路径;
+- 托管端点和 OpenAI 兼容的自建端点需要共享访问层;
+- API 与 AI 流量需要共用网关运维和可观测体系。
-### 2. 可观测性
-
-- **用量追踪**:细粒度 Token 消耗监控,支撑成本分析与容量规划
-- **审计日志**:完整记录 AI 交互轨迹,满足合规审计需求
-- **实时监控**:跟踪 LLM 响应时间、错误率和 API 使用模式等关键 SLA 指标,以确保达到理想的性能状态
+只调用单个供应商的原型应用未必需要立即部署专用网关。随着应用、供应商、环境和共享策略增加,网关的价值会更加明显。
-### 3. 提示词工程
-
-- **检索增强生成(RAG)**:通过检索增强生成技术提升响应准确率
-- **提示词装饰器和模板**:标准化提示词模板实现跨场景最佳实践复用
-- **动态上下文注入**:基于会话上下文智能补充查询语义
+## AI 网关与 API 网关的关系
-### 4. 可靠性
-
-- **多模型负载均衡**:智能分发请求至最优 LLM 实例
-- **重试与降级机制**:在 AI 服务异常时实现优雅降级
-- **流量分级调度**:保障高优先级任务的服务质量(QoS)
+AI 网关与 API 网关在路由、身份认证、限流、故障处理和可观测性上存在重叠。AI 网关进一步增加适用于模型流量的控制,例如 Token 限制、模型供应商请求转换、提示词处理和 LLM 用量摘要。
-## 总结
-
-AI 与业务系统的深度整合既是机遇也是挑战。当 AI 服务主要通过 API 进行交互时,构建专用的 AI 网关成为技术架构演进的关键路径。通过在传统 API 网关基础上叠加 AI 专属能力,企业能够实现:
-
-**✅ 安全闭环**:构建从数据输入到内容输出的全链路防护
+Apache APISIX 使用同一个开源网关处理普通 API 流量和已配置的 AI 流量。团队可以增加 AI 专用插件,而不必只为模型调用引入另一层网络基础设施。更直接的能力对比请参阅 [AI 网关 vs API 网关](/zh/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained/)。
-**✅ 成本可控**:通过 Token 计量与缓存机制优化资源利用率
-
-**✅ 体验升级**:基于智能路由策略保障毫秒级响应体验
+## 总结
-**✅ 运维提效**:统一监控面板实现多模型服务治理
+AI 网关集中管理应用和模型供应商之间的网络层控制。它的实际价值不是自主决策,而是一致的供应商访问、路由、Token 限制、提示词处理、故障处理策略和网关遥测。
-随着 AI 技术持续演进,AI 网关将逐步成为智能时代的技术基座。率先构建 AI 网关能力的企业,将在保障 AI 服务可靠性的同时,获得技术架构的长期竞争优势,为业务创新提供持续动能。
+Apache APISIX 通过有明确文档的开源插件提供这些控制,并把业务授权、Agent 编排、工作流状态和模型评估留给真正负责这些职责的系统。
diff --git a/blog/zh/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md b/blog/zh/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
index 8eb77b7cc9a77..e2e3f7658fcc7 100644
--- a/blog/zh/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
+++ b/blog/zh/blog/2025/03/21/ai-gateway-vs-api-gateway-differences-explained.md
@@ -1,5 +1,5 @@
---
-title: "AI 网关解析:与传统 API 网关的核心差异"
+title: "AI 网关 vs API 网关:核心差异与选择方法"
authors:
- name: Yilia Lin
title: Technical Writer
@@ -8,162 +8,119 @@ authors:
keywords:
- AI 网关
- API 网关
- - LLM
- - APISIX AI 网关
+ - 大语言模型
+ - 生成式 AI
- Apache APISIX
- - API 货币化
- - MCP
- - 模型上下文协议
+ - Token 用量
- 流式请求
-description: 本文深入解析 AI 网关的技术特性,探讨其与传统 API 网关的本质区别,并阐述为何 Apache APISIX AI Gateway 等演进式解决方案代表未来趋势。
+ - 模型路由
+description: "从流量模式、路由、Token 控制、流式响应、安全和运维等方面比较 AI 网关与 API 网关,并了解何时使用二者。"
+image: https://static.api7.ai/uploads/2025/03/21/TIySzjk5_ai-gateway-vs-api-gateway.webp
tags: [Ecosystem]
---
-> “未来的方向不是独立的 AI 网关,而是具备 AI 交互能力的 API 网关。” 本文深入解析 AI 网关的技术特性,探讨其与传统 API 网关的本质区别,并阐述为何 [Apache APISIX AI Gateway](https://apisix.apache.org/zh/blog/2025/02/24/apisix-ai-gateway-features/) 等演进式解决方案代表未来趋势。
+API 网关管理通用 API 流量,AI 网关则增加面向大语言模型(LLM)和其他 AI 服务的流量控制。两者存在重叠:AI 网关同样需要路由、身份认证、限流、故障处理和可观测性,同时还要处理模型供应商、Token、提示词和流式模型响应。
-## 什么是 AI 网关?它为何在 AI 时代兴起?
+## AI 网关与 API 网关概览
-AI 时代带来了前所未有的复杂性,企业需要在不同环境(云端、边缘、混合架构)中管理多个 AI 模型,包括计算机视觉、大语言模型(LLM)等。传统 API 网关专注于通用数据流量,难以满足 AI 工作负载的特殊需求。因此,AI 网关应运而生,作为统一的控制平面,用于路由、保护和优化 AI 任务。
+| 维度 | API 网关 | AI 网关 |
+| --- | --- | --- |
+| 主要上游 | Web API 和微服务 | 模型供应商和 AI 服务 |
+| 用量单位 | 请求、连接或字节 | 请求以及输入、输出 Token |
+| 路由 | Host、路径、Header、权重和服务健康状态 | 通用控制,加上配置型模型实例或供应商路由 |
+| 请求处理 | 通用协议和载荷策略 | 供应商请求转换和提示词处理 |
+| 响应模式 | 同步、异步或流式 API | 常见长时间运行或流式模型响应 |
+| 故障处理 | 重试、超时、熔断和上游健康检查 | 类似控制,加上模型供应商 fallback 和 Token 相关约束 |
+| 可观测性 | 请求速率、延迟、状态、日志和追踪 | 网关指标,以及能力支持时的模型、Token 和首 Token 延迟摘要 |
-## AI 网关的兴起
+这种区别描述的是额外工作负载和策略,并不意味着必须部署独立产品。有些组织使用专用 AI 网关,另一些组织则在已有 API 网关上增加 AI 专用插件。
-生成式 AI 和 LLM 的普及带来了独特挑战:
+## API 网关负责什么
-- **Token 计费**:LLM 以 Token 为单位处理请求,需要精细化管理成本和性能。
+API 网关位于客户端和后端服务之间,提供统一入口并实施共享流量策略,例如:
-- **流式请求**:AI 代理通常返回流式数据(例如 ChatGPT 的增量输出),需要低延迟处理。
+- 请求路由和负载均衡;
+- 网关侧身份认证;
+- 限流与流量整形;
+- TLS 终止和网络层访问控制;
+- 重试、超时和熔断;
+- 网关日志、指标和链路追踪集成。
-- **工具集成**:AI 需要外部数据源(如实时天气数据、CRM 记录)进行推理。
+这些控制可以减少各 API 重复实现基础设施逻辑。业务授权、资源级权限、领域行为和服务特定遥测仍由服务负责。
-Gartner 2023 年报告显示,75% 以上企业已在生产环境部署 AI 模型,专用基础设施需求激增。传统 API 网关基于 RESTful API 和静态请求响应设计,难以适配 AI 特性需求,专用 AI 网关应运而生。
+## AI 网关增加了什么
-## AI 代理 vs. 传统设备:流式请求为何需要专门处理?
+[AI 网关](/zh/blog/2025/03/06/what-is-an-ai-gateway/)将网关控制用于模型流量,并增加符合 LLM 服务特点的能力。
-AI 代理(如聊天机器人、代码助手)产生的流量模式与传统客户端截然不同:
+### 供应商请求转换
-指标| 传统 API 请求| AI 代理请求
----|---|---
-请求类型| 同步(HTTP GET/POST)| 异步、流式(SSE)
-延迟| 毫秒| 秒 - 分钟(用于分块)
-计费| 每 API 调用| 每 Token 或计算时间
-故障模式| 超时、HTTP 错误| 部分完成、幻觉
+模型供应商可能使用不同的端点、凭证和请求格式。AI 网关可以向应用提供稳定入口,并为其支持的供应商转换请求。实际兼容性仍取决于所选供应商和网关实现。
-### 流式请求的技术挑战
+### 配置型模型路由与 Fallback
-当 AI 代理请求由 GPT - 4 生成一首诗歌时,响应是增量式流式传输的。传统 API 网关面临以下问题:
+AI 网关可以按照权重或一致性哈希等明确策略,在模型实例之间分配请求。有些实现还提供有限重试、健康检查或 fallback 策略。
-- **部分响应**:将分片的数据整合到审计日志中。
-- **Token 计数**:准确统计流式传输分块中的 Token 数量。
-- **实时可观测性**:按 Token 监控延迟或检测响应质量的漂移。
+这属于网络流量管理,而不是自主模型选择。除非网关明确提供且配置了相应能力,否则判断哪个模型最适合某项任务、评估回答质量并根据业务结果改变路由,需要由应用逻辑或独立评估系统负责。
-许多专用 AI 网关缺乏分布式追踪能力,导致工程师需要手动拼接数据。而 Apache APISIX 这样的 API 网关原生支持 Prometheus 和 Grafana,可提供 Token 级别的可观测性。
+### Token 感知的限制
-## AI 网关的两大类型:专用 AI 网关 vs. API 网关的 AI 演进
+传统限流统计单位时间内的请求数。LLM 工作负载还可能需要根据输入和输出 Token 设限,因为不同请求的大小和成本差异很大。Token 控制可以在网关限制用量,但定价、预算和成本分摊仍由外部系统负责。
-目前的 AI 网关主要分为两类:
+### 提示词与内容控制
-### 专用 AI 网关
+AI 网关可能分别提供提示词模板、提示词装饰、基于模式的提示词检查、内容审核或检索增强。每项能力都有明确范围。提示词规则或审核集成不能替代应用授权、数据治理、模型评估或合规审查。
-这类网关从零开始构建,专门解决 AI 相关问题,例如:
+### AI 流量遥测
-- **基于 Token 速率限制**:按照 Token 数量(而非 API 调用次数)进行配额管理。
+如果供应商响应提供所需数据,AI 网关可以记录模型名称、Token 用量、请求耗时和首个 Token 返回时间。网关遥测补充应用链路追踪和供应商监控,但无法单独衡量最终用户满意度、回答正确性或幻觉率。
-- **Prompt 工具**:帮助开发者调试和优化 Prompt。
+## 流式响应并非 AI 独有
-- **AI 分析**:追踪幻觉率、Token 成本等 AI 相关指标。
+LLM 应用常使用 Server-Sent Events(SSE)增量返回生成内容,但流式传输并非 AI 独有。传统 API 同样可以使用 SSE、WebSocket 或其他流式模式,而且部分模型调用也是同步的。
-示例:OpenAI API 采用 Token 计费(GPT-4 费用为 $0.06/千 Token),因此网关需要精准计量 Token 使用情况。然而,这类网关通常在可观测性和可扩展性上不如成熟的 API 网关。例如,跨多个微服务统计 Token 消耗可能会因缺乏分布式追踪能力而不准确。
+实际区别在于模型流可能持续更长时间,并且用量信息可能要到响应完成后才可获得。团队应先验证网关如何处理流式响应、超时、重试、日志和部分响应,再决定是否沿用短 Web 请求的策略。
-### 由 API 网关演进而来的 AI 网关
+## 什么时候使用 API 网关
-成熟的 API 网关(如 Kong、Apache APISIX、AWS API Gateway)正逐步适配 AI 需求,新增能力包括:
+当主要需求是为 Web API 或微服务提供统一入口和流量策略时,应使用 API 网关。典型场景包括:
-- **流式数据支持**:兼容 Server-Sent Events(SSE)、WebSocket,支持 AI 实时响应。
+- 在后端服务之间路由请求;
+- 集中实施网关身份认证和限流;
+- 在 Kubernetes、虚拟机或混合环境中公开 API;
+- 应用共享的故障处理和可观测性控制。
-- **Token 感知插件**:扩展限流插件,以 Token 维度进行计费和限流。
+即使组织没有 LLM 工作负载,API 网关仍然有价值。
-- **LLM 调度**:管理多个 AI 模型,例如为简单任务优先分配低成本模型(如 Mistral-7B)。
+## 什么时候增加 AI 网关能力
-这些 API 网关依托多年积累的安全(OAuth、JWT)、扩展性(负载均衡)和商业化能力(流量变现),在 AI 时代具备更大的适应性,而这些特性在许多专用 AI 网关中仍然缺失。
+当模型流量产生普通请求策略无法覆盖的需求时,可以增加 AI 网关能力,例如:
-## 为什么演进型 AI 网关能笑到最后
+- 多个应用需要共享模型供应商访问层;
+- 团队除请求限流外还需要基于 Token 的限制;
+- 模型实例需要配置型负载均衡、重试或 fallback;
+- 提示词模板、提示词检查、审核或受支持的 RAG 处理需要在网关执行;
+- 运维人员需要在现有网关遥测中查看模型和 Token 摘要。
-尽管专用 AI 网关在特定场景下表现出色,但演进型 API 网关正在成为主流选择,主要有以下三点原因:
+只调用一个模型供应商的应用未必需要立即部署专用 AI 网关。随着应用、供应商、环境和共享策略数量增加,网关的运维价值会更明显。
-- **成本效益**:分别维护 AI 流量和非 AI 流量的网关会导致运营成本翻倍。融合系统可降低 30%–50% 的成本(Gartner,2023)。
+## 使用同一网关处理 API 与 AI 流量
-- **灵活性**:企业无法预测未来哪种 AI 模型会占主导地位。Apache APISIX 等平台支持无缝集成新 LLM,而无需重新架构系统。
+Apache APISIX 是开源 API 网关,也可以通过插件实施 AI 专用控制。其通用网关能力处理路由、身份认证、故障策略和可观测性,AI 插件则增加供应商代理、配置型多模型路由、Token 限制、提示词处理、检索增强和 AI 流量摘要。
-- **未来适应性**:随着 AI 深入各类应用(如电商中的 AI 搜索),网关必须具备处理混合工作负载的能力。
+例如:
-## 模型上下文协议(MCP):连接 AI 助手与外部工具
+- [`ai-proxy`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy/) 连接文档列出的模型供应商和 OpenAI 兼容端点。
+- [`ai-proxy-multi`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-proxy-multi/) 在模型实例之间提供配置型负载均衡、重试、fallback 和健康检查。
+- [`ai-rate-limiting`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rate-limiting/) 执行基于 Token 的用量限制。
+- [`ai-prompt-guard`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-prompt-guard/) 根据配置模式允许或拒绝提示词。
+- [`ai-rag`](https://apisix.apache.org/zh/docs/apisix/plugins/ai-rag/) 提供文档支持的 Azure OpenAI 与 Azure AI Search 检索流程。
-为了让 AI 代理顺畅访问外部数据和 API,**[模型上下文协议(Model Context Protocol, MCP)](https://github.com/modelcontextprotocol)** 正逐步成为行业标准。MCP 规范了 AI 模型如何请求并使用外部资源,例如:
+这种方式让团队可以复用同一套网关运维模式,同时不会把 APISIX 描述成应用运行时或完整的 AI 治理平台。[Apache APISIX AI 网关概览](/zh/ai-gateway/)进一步列出了工作负载需求及其对应插件。
-- **数据源**:SQL 数据库、向量存储(如 Pinecone)。
+## 总结
-- **API**:CRM 系统、支付网关。
+API 网关和 AI 网关解决的是相互重叠的流量管理问题。API 网关提供适用于 API 和微服务的通用基础;AI 网关增加供应商、Token、提示词、检索和模型遥测控制。
-- **工具**:代码解释器、图像生成器。
-
-### MCP 运行方式
-
-- **上下文注入**:AI 助手在请求中附带一个上下文头,指定所需的工具(如 `MCP-Context: weather_api, crm`)。
-
-- **网关路由**:AI 网关验证权限、注入 API Key,并将请求路由到相应的服务。
-
-- **响应合成**:网关聚合 API 返回的数据(如天气数据 + CRM 客户信息),再传递给 AI 模型。
-
-### 示例
-
-用户请求:“给我们在纽约的头部客户发送一封邮件,告知他今天的天气。”
-
-AI 网关使用 MCP 进行以下操作:
-
-1. 从 Salesforce 获取该客户的信息。
-2. 从 OpenWeatherMap 获取纽约的天气数据。
-3. 将这些信息传递给 GPT-4,生成邮件内容。
-
-### MCP 的优势
-
-1. **安全性**:集中策略控制,例如在 CRM 响应中屏蔽 PII(个人身份信息)。
-
-2. **成本控制**:缓存常见数据请求(如产品目录),降低 API 访问成本。
-
-3. **互操作性**:标准化 AI 与 API 之间的通信方式,提高跨供应商的兼容性。
-
-## AI 网关的未来:与 API 货币化的融合
-
-随着 AI 采用的成熟,两大趋势将塑造 AI 网关:
-
-### 趋势 1:独立 AI 网关逐渐式微
-
-专门的 AI 网关将难以与演进型 API 网关竞争,后者具备:
-
-- **统一治理**:支持 REST、GraphQL 和 AI API 的综合平台。
-
-- **变现模式**:支持基于 Token 的计费和订阅模式。
-
-- **企业级特性**:提供基于角色的访问控制(RBAC)、审计日志等。
-
-在这种趋势下,AI 流量将逐步迁移到具备 AI 处理能力的传统 API 网关。
-
-### 趋势 2:API 网关作为 AI 编排器
-
-未来的 API 网关将不仅是流量管理工具,还将成为 AI 编排器,具备:
-
-- **模型路由**:根据成本、延迟、准确性,将请求分配给最优 AI 模型。
-
-- **混合工作流**:融合 AI 与非 AI 服务(如对 GPT-4 的响应进行数据库验证)。
-
-- **Token 分析**:提供实时仪表盘,按团队或项目统计 Token 消耗情况。
-
-## 拥抱 AI 与 API 的融合
-
-AI 网关不是 API 网关的替代品,而是其演进形态。尽管专用 AI 解决方案能满足短期 LLM 需求,但由于可观测性和可扩展性的不足,它们只是过渡方案。
-
-成熟的 API 网关,如 Apache APISIX AI Gateway,通过流式处理、Token 计费插件、MCP 适配等增强 AI 能力,正在成为行业主流。随着 AI 逐步嵌入各类应用,企业应选择可扩展的平台,以避免被孤立在特定 AI 生态中。
-
-最终的赢家?将是那些能够兼容 API 与 AI 的高适配、可扩展网关解决方案。
+团队应根据工作负载所需策略做选择。组织可以根据技术或组织边界部署独立网关,也可以使用 Apache APISIX,在同一个开源平台中管理普通 API 和已配置的 AI 流量。
diff --git a/blog/zh/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md b/blog/zh/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
index 49fffdc976359..0c845a0347331 100644
--- a/blog/zh/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
+++ b/blog/zh/blog/2026/07/10/manage-apache-apisix-with-ai-agents.md
@@ -84,5 +84,5 @@ AI 智能体正在成为操作基础设施的一种重要交互界面。用开
## 延伸阅读
-- [Apache APISIX AI Gateway](https://apisix.apache.org/ai-gateway/)——LLM 代理、负载均衡、基于 token 的限流,以及 MCP 支持
+- [Apache APISIX AI Gateway](https://apisix.apache.org/zh/ai-gateway/)——LLM 代理、负载均衡、基于 Token 的限流、提示词控制和网关层可观测能力
- [Apache APISIX 的 AI Agent Skills](https://docs.api7.ai/apisix/ai-agent-skills)——完整的、可搜索的 skills 目录
diff --git a/next/public/img/ai-gateway/ai-cache.svg b/next/public/img/ai-gateway/ai-cache.svg
new file mode 100644
index 0000000000000..ef31dc7d9f06f
--- /dev/null
+++ b/next/public/img/ai-gateway/ai-cache.svg
@@ -0,0 +1,19 @@
+
diff --git a/next/src/components/HomePage.astro b/next/src/components/HomePage.astro
index 415c2884977bf..3da8487b33d62 100644
--- a/next/src/components/HomePage.astro
+++ b/next/src/components/HomePage.astro
@@ -28,7 +28,7 @@ const QUICK_CARDS = [
const AI_PROVIDERS = ['OpenAI', 'Anthropic', 'AWS Bedrock', 'DeepSeek', 'Ollama', '+ more'];
// title, description, doc link. Mirrors website/src/.../AIGatewaySection.tsx.
const AI_CARDS: [string, string, string][] = [
- ['Multi-LLM proxy', 'Route to OpenAI, Anthropic, AWS Bedrock, DeepSeek, Ollama and 20+ providers through one endpoint.', '/docs/apisix/plugins/ai-proxy/'],
+ ['Multi-LLM proxy', 'Proxy requests to documented providers and OpenAI-compatible endpoints through one gateway.', '/docs/apisix/plugins/ai-proxy/'],
['LLM load balancing', 'Distribute traffic across providers and models for throughput and resilience.', '/docs/apisix/plugins/ai-proxy-multi/'],
['Retry & fallback', 'Fail over to a backup model or provider automatically when one is unavailable.', '/docs/apisix/plugins/ai-proxy-multi/'],
['Token rate limiting', 'Cap usage and cost with token-based rate limits per consumer.', '/docs/apisix/plugins/ai-rate-limiting/'],
@@ -179,8 +179,8 @@ const SOFTWARE_APPLICATION_SCHEMA = {
AI Gateway
{t(locale, 'The same gateway, now for your LLM traffic', '同一个网关,现在服务你的 LLM 流量')}
{t(locale,
- 'Proxy, secure, and govern traffic to 20+ LLM providers — with the performance, plugins, and observability you already run for your APIs.',
- '代理、保护并治理发往 20+ LLM 提供商的流量——复用你已经在 API 上运行的性能、插件与可观测能力。')}
+ 'Proxy, secure, and govern traffic to documented LLM providers and OpenAI-compatible endpoints with the plugins and observability you already use for APIs.',
+ '代理、保护并治理发往文档所列 LLM 提供商及 OpenAI 兼容端点的流量,复用你已用于 API 的插件与可观测能力。')}
{t(locale, 'AI apps & agents', 'AI 应用与智能体')}→Apache APISIX→
diff --git a/next/src/components/MainPages/AiGatewayPage.astro b/next/src/components/MainPages/AiGatewayPage.astro
index 11530f0cae14f..d9e9a649f3c70 100644
--- a/next/src/components/MainPages/AiGatewayPage.astro
+++ b/next/src/components/MainPages/AiGatewayPage.astro
@@ -11,55 +11,119 @@ const features = [
title: t(locale, 'Multi-LLM load balancing', '多 LLM 负载均衡'),
description: t(
locale,
- 'Route across OpenAI, DeepSeek, Claude, Mistral, Gemini, and other providers with health checks and weighted balancing.',
- '通过健康检查和权重负载均衡,在 OpenAI、DeepSeek、Claude、Mistral、Gemini 等模型提供商之间路由。',
+ 'Use weighted round robin or consistent hashing, or configure semantic routing from prompt similarity to per-instance examples.',
+ '使用加权轮询或一致性哈希,或根据提示词与各实例示例的相似度配置语义路由。',
),
icon: '/img/ai-gateway/load-balancing.svg',
+ href: '/docs/apisix/plugins/ai-proxy-multi/',
},
{
title: t(locale, 'Token rate limiting', 'Token 限流'),
description: t(
locale,
- 'Control token consumption by Route, Service, Consumer, Consumer Group, or custom attributes in standalone and cluster deployments.',
- '按 Route、Service、Consumer、Consumer Group 或自定义属性控制 token 消耗,支持单机与集群部署。',
+ 'Track provider-reported token usage with local or Redis-backed counters, then reject subsequent requests after the configured quota is consumed.',
+ '使用本地或 Redis 计数器记录提供商返回的 token 用量,并在配置额度耗尽后拒绝后续请求。',
),
icon: '/img/ai-gateway/token-rate-limiting.svg',
+ href: '/docs/apisix/plugins/ai-rate-limiting/',
},
{
title: 'AI RAG',
description: t(
locale,
- 'Connect enterprise knowledge to model requests at the gateway layer for grounded, context-aware responses.',
- '在网关层为模型请求连接企业知识库,生成有依据、具备上下文的响应。',
+ 'Augment requests with context retrieved through the plugin\'s documented Azure OpenAI and Azure AI Search integration.',
+ '通过插件当前支持的 Azure OpenAI 与 Azure AI Search 集成,为请求补充检索到的上下文。',
),
icon: '/img/ai-gateway/ai-rag.svg',
+ href: '/docs/apisix/plugins/ai-rag/',
},
{
title: t(locale, 'Token observability', 'Token 可观测性'),
description: t(
locale,
- 'Track token usage through access logs and existing observability tools to control abuse and unexpected cost.',
- '通过访问日志和现有可观测工具追踪 token 使用,控制滥用和意外成本。',
+ 'Record model, latency, token usage, and time-to-first-token summaries when AI proxy logging is enabled.',
+ '启用 AI 代理日志后,记录模型、延迟、token 用量和首 token 响应时间等摘要。',
),
icon: '/img/ai-gateway/observability.svg',
+ href: '/docs/apisix/plugins/ai-proxy/',
},
{
title: t(locale, 'Retry and fallback', '重试与回退'),
description: t(
locale,
- 'Use health checks, automatic retries, and fallback providers to keep AI applications available when an upstream model fails.',
- '通过健康检查、自动重试和备用模型提供商,在上游模型故障时保持 AI 应用可用。',
+ 'Configure bounded retries and fallback strategies for selected upstream failures without changing application endpoints.',
+ '针对指定的上游故障配置有限次数的重试和回退策略,无需更改应用访问端点。',
),
icon: '/img/ai-gateway/retry-fallback.svg',
+ href: '/docs/apisix/plugins/ai-proxy-multi/',
},
{
- title: t(locale, 'Prompt security', '提示词安全'),
+ title: t(locale, 'Prompt and content controls', '提示词与内容控制'),
description: t(
locale,
- 'Apply prompt guards, decorators, templates, content moderation, logging, and auditing before traffic reaches a model.',
- '在流量到达模型之前应用提示词防护、装饰、模板、内容审核、日志和审计。',
+ 'Apply allow and deny patterns with Prompt Guard, and compose separate plugins for templates, decoration, or moderation.',
+ '使用 Prompt Guard 配置允许与拒绝规则,并按需组合模板、装饰或内容审核插件。',
),
icon: '/img/ai-gateway/security.svg',
+ href: '/docs/apisix/plugins/ai-prompt-guard/',
+ },
+ {
+ title: t(locale, 'AI response caching', 'AI 响应缓存'),
+ description: t(
+ locale,
+ 'With ai-proxy or ai-proxy-multi, cache completed LLM responses using Redis-backed exact matching and optional semantic matching.',
+ '与 ai-proxy 或 ai-proxy-multi 配合,使用 Redis 支持的精确匹配和可选语义匹配缓存完整的 LLM 响应。',
+ ),
+ icon: '/img/ai-gateway/ai-cache.svg',
+ href: '/docs/apisix/plugins/ai-cache/',
+ },
+ {
+ title: t(locale, 'Lakera Guard integration', 'Lakera Guard 集成'),
+ description: t(
+ locale,
+ 'With ai-proxy or ai-proxy-multi, use the Lakera Guard v2 API to inspect supported LLM requests, responses, or both.',
+ '与 ai-proxy 或 ai-proxy-multi 配合,使用 Lakera Guard v2 API 检查受支持的 LLM 请求、响应或两者。',
+ ),
+ icon: '/img/ai-gateway/security.svg',
+ href: '/docs/apisix/plugins/ai-lakera-guard/',
+ },
+];
+
+const capabilities = [
+ {
+ need: t(locale, 'Connect to model providers', '连接模型提供商'),
+ plugin: 'ai-proxy',
+ description: t(locale, 'Proxy requests to documented providers and OpenAI-compatible endpoints.', '代理请求到文档列出的提供商及 OpenAI 兼容端点。'),
+ },
+ {
+ need: t(locale, 'Route across model instances', '在模型实例间路由'),
+ plugin: 'ai-proxy-multi',
+ description: t(locale, 'Configure load balancing or semantic routing; retry and health-check behavior depends on the selected algorithm.', '配置负载均衡或语义路由;重试和健康检查行为取决于所选算法。'),
+ },
+ {
+ need: t(locale, 'Control token consumption', '控制 token 消耗'),
+ plugin: 'ai-rate-limiting',
+ description: t(locale, 'Count provider-reported token usage and reject subsequent requests after the configured quota is consumed.', '记录提供商返回的 token 用量,并在配置额度耗尽后拒绝后续请求。'),
+ },
+ {
+ need: t(locale, 'Add retrieval context', '增加检索上下文'),
+ plugin: 'ai-rag',
+ description: t(locale, 'Use the documented Azure OpenAI and Azure AI Search RAG flow.', '使用文档支持的 Azure OpenAI 与 Azure AI Search RAG 流程。'),
+ },
+ {
+ need: t(locale, 'Check prompt patterns', '检查提示词规则'),
+ plugin: 'ai-prompt-guard',
+ description: t(locale, 'Allow or deny requests using configured regular-expression patterns.', '使用已配置的正则表达式规则允许或拒绝请求。'),
+ },
+ {
+ need: t(locale, 'Cache completed responses', '缓存完整响应'),
+ plugin: 'ai-cache',
+ description: t(locale, 'Pair with ai-proxy or ai-proxy-multi for Redis-backed exact and optional semantic caching.', '与 ai-proxy 或 ai-proxy-multi 配合,实现 Redis 支持的精确缓存和可选语义缓存。'),
+ },
+ {
+ need: t(locale, 'Inspect supported AI traffic', '检查受支持的 AI 流量'),
+ plugin: 'ai-lakera-guard',
+ description: t(locale, 'Pair with ai-proxy or ai-proxy-multi to inspect supported traffic through the Lakera Guard v2 API.', '与 ai-proxy 或 ai-proxy-multi 配合,通过 Lakera Guard v2 API 检查受支持的流量。'),
},
];
@@ -70,8 +134,8 @@ const pageTitle = t(
);
const description = t(
locale,
- 'Use Apache APISIX as an open-source LLM gateway and proxy for model routing, load balancing, retries, fallback, token rate limiting, security, and observability.',
- '使用 Apache APISIX 构建开源 LLM 网关与代理,提供模型路由、负载均衡、重试、回退、token 限流、安全和可观测能力。',
+ 'Use Apache APISIX as an open-source AI and LLM gateway for multi-provider proxying, load balancing, retries, token limits, prompt controls, RAG, and gateway-level observability.',
+ '使用 Apache APISIX 构建开源 AI 与 LLM 网关,提供多提供商代理、负载均衡、重试、token 限制、提示词控制、RAG 和网关层可观测能力。',
);
---
{t(
locale,
- 'Open-source data plane, open plugin model, and portable configuration for APIs and AI workloads.',
- '开源数据面、开放插件模型和可移植配置,同时服务 API 与 AI 工作负载。',
+ 'Run the Apache 2.0-licensed gateway in infrastructure you control and extend it through its open plugin model.',
+ '在自主管理的基础设施中运行 Apache 2.0 许可的网关,并通过开放插件模型进行扩展。',
)}
@@ -134,8 +198,8 @@ const description = t(
{t(locale, 'Open AI plugin ecosystem', '开放的 AI 插件生态')}
{t(
locale,
- 'Load balancing, fallback, token controls, RAG, prompt policies, moderation, and auditing are all available as open-source plugins.',
- '负载均衡、回退、token 控制、RAG、提示词策略、内容审核和审计均以开源插件提供。',
+ 'Compose documented AI plugins for provider access, routing, token controls, retrieval augmentation, prompt processing, moderation, and gateway logging.',
+ '按需组合已有文档的 AI 插件,实现提供商接入、路由、token 控制、检索增强、提示词处理、内容审核和网关日志。',
)}
+
+
+
+
{t(locale, 'AI Gateway explained', 'AI 网关解析')}
+
{t(locale, 'What is an AI gateway?', '什么是 AI 网关?')}
+
{t(
+ locale,
+ 'An AI gateway is a traffic control layer between applications and model providers. It gives teams one place to apply provider access, routing, usage limits, prompt processing, and telemetry to model requests.',
+ 'AI 网关是位于应用与模型提供商之间的流量控制层,让团队可以集中为模型请求配置提供商接入、路由、用量限制、提示词处理和遥测能力。',
+ )}
+
{t(
+ locale,
+ 'Apache APISIX applies configured policies to AI and LLM traffic that passes through the gateway. Application authorization, tool selection, workflow state, agent orchestration, and model-quality evaluation remain responsibilities of the surrounding application stack.',
+ 'Apache APISIX 对经过网关的 AI 与 LLM 流量应用已配置的策略。应用授权、工具选择、工作流状态、Agent 编排和模型质量评估仍由外围应用技术栈负责。',
+ )}
{t(locale, 'Route to the model that fits each request', '为每个请求选择合适的模型')}
+
{t(locale, 'Connect supported and OpenAI-compatible providers', '连接已支持及 OpenAI 兼容的提供商')}
{t(
locale,
- 'Use OpenAI, DeepSeek, Claude, Mistral, Gemini, self-hosted models, or a mix of providers without changing the application-facing gateway.',
- '使用 OpenAI、DeepSeek、Claude、Mistral、Gemini、自托管模型或多提供商组合,无需改变应用侧网关。',
+ 'Connect the providers documented by the AI Proxy plugin, or use an OpenAI-compatible endpoint for additional hosted or self-managed services. Provider selection follows the routing policy you configure.',
+ '连接 AI Proxy 插件文档列出的提供商,或通过 OpenAI 兼容端点接入其他托管或自主管理的服务。提供商选择由你配置的路由策略决定。',
)}
 +