


The default settings are costing you money. token-max replays your Claude Code and Codex transcripts under other settings, at API prices, and shows which ones to change. Run this:
curl -LsSf https://max.kixel.ai/run.sh | shOn Windows, irm https://max.kixel.ai/run.ps1 | iex. It changes nothing
without a yes.
On the maintainer's last 30 days across four machines, replayed 2026-11-18:
| API cost | Sessions | Potential savings |
|---|---|---|
| ~$70,508 | 12,176 | ~$5,653/mo |
That is 1,190,393 Claude Code, Codex and T3 Code requests at public API
prices. The savings are what token-max doctor --defaults finds for a user
with no settings files on the same history: every change it would make, 8%
of the spend. Most of it is a 1h subagent cache; the rest is a 1h main-agent
cache on usage credits, auto memory and unused skills and tools.
- Subagents: a 1h prompt cache cost ~17% less than the default 5m, ~$3,940/mo
of those savings. Every Claude Code user's subagents get 5m. The setting is
subagentPromptCacheTtl. - Main agent on an API key or usage credits: 1h cost ~37% less than 5m,
~$518/mo of those savings. A plan's included usage already gets 1h; API keys
and usage credits get 5m. The setting is
promptCacheTtl.
~ marks figures extrapolated over requests that could not be priced. The full results have each machine, the margins and how this compares with T3 Code's own count. Your sessions differ: run it to see yours.
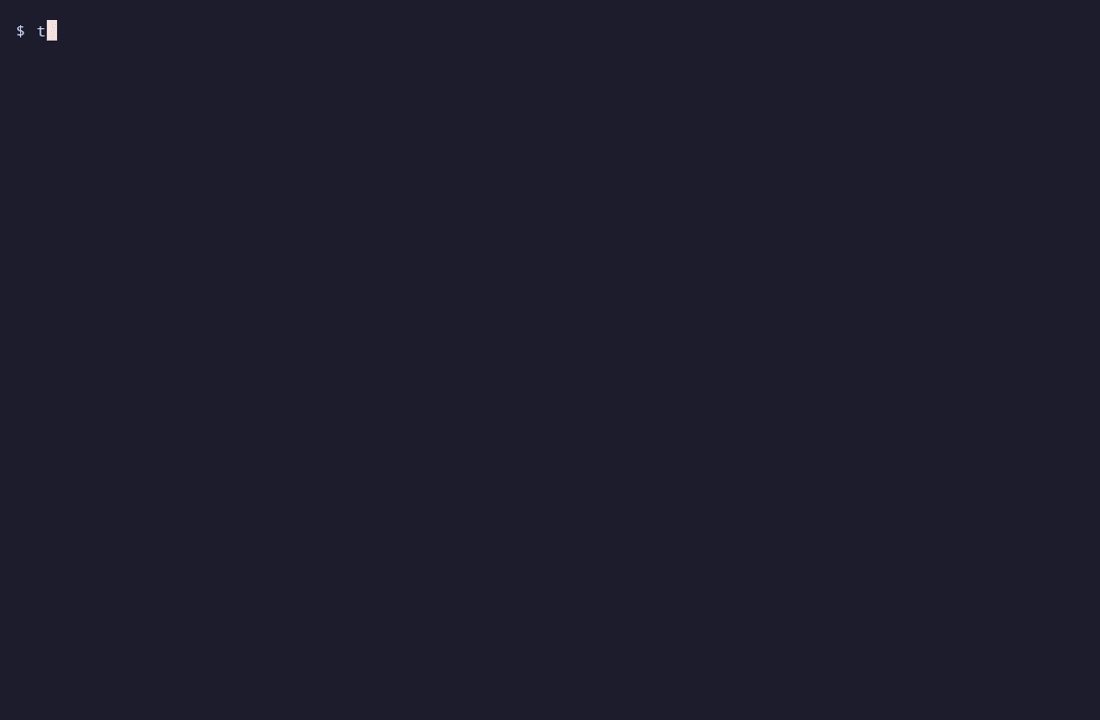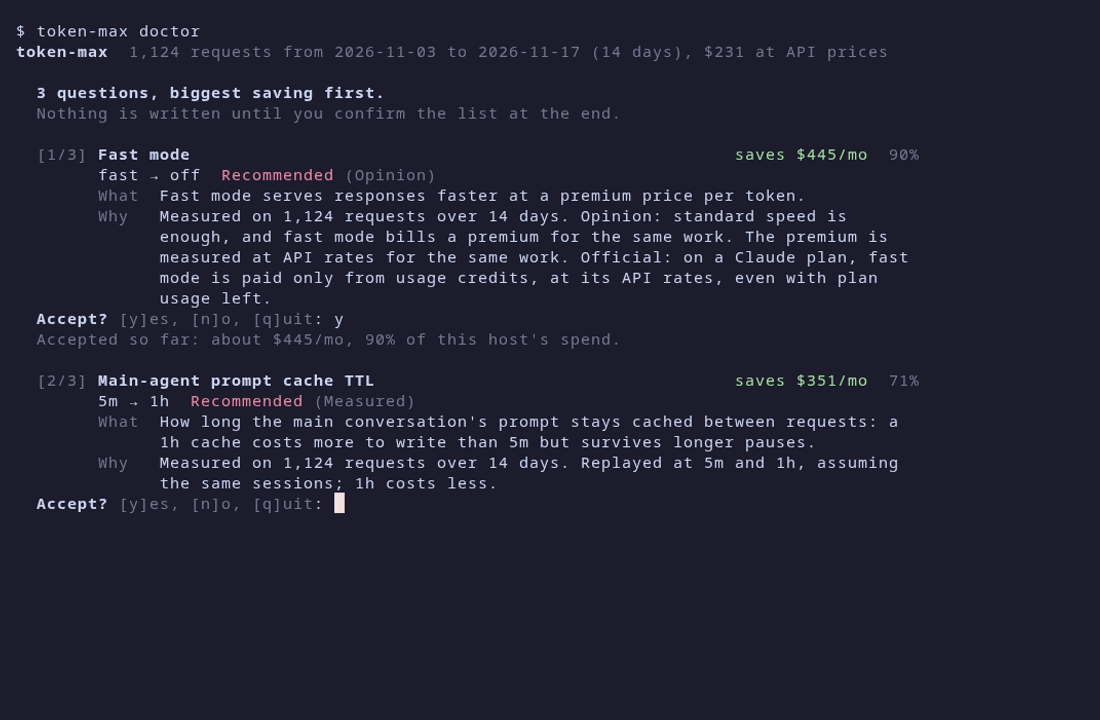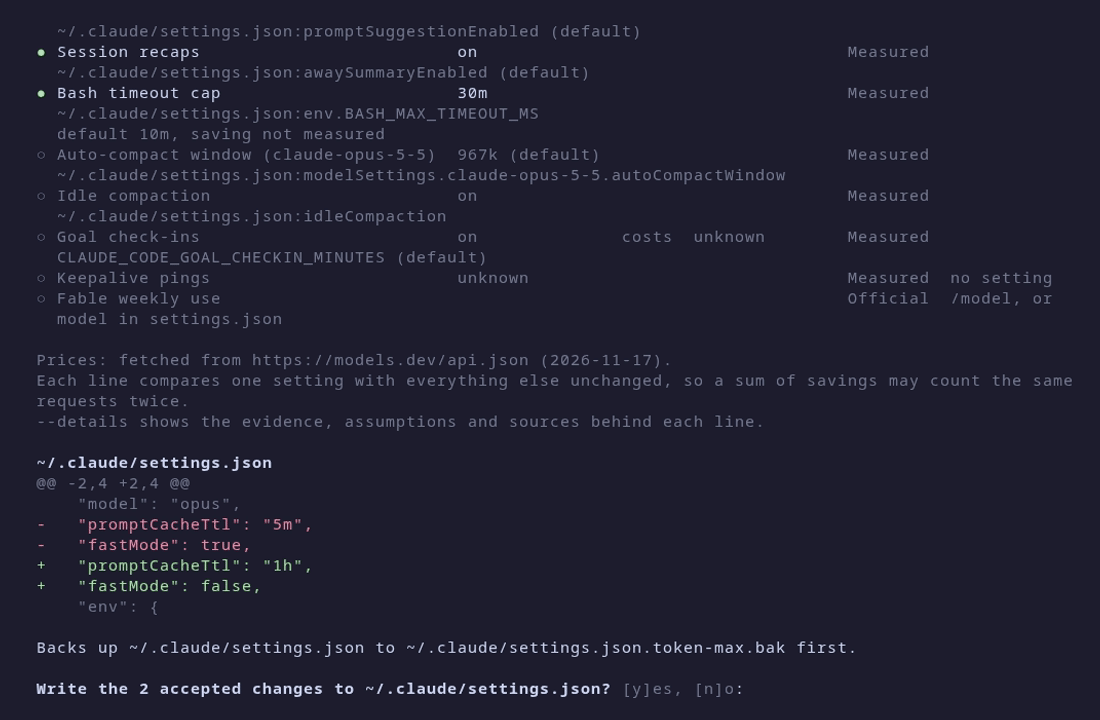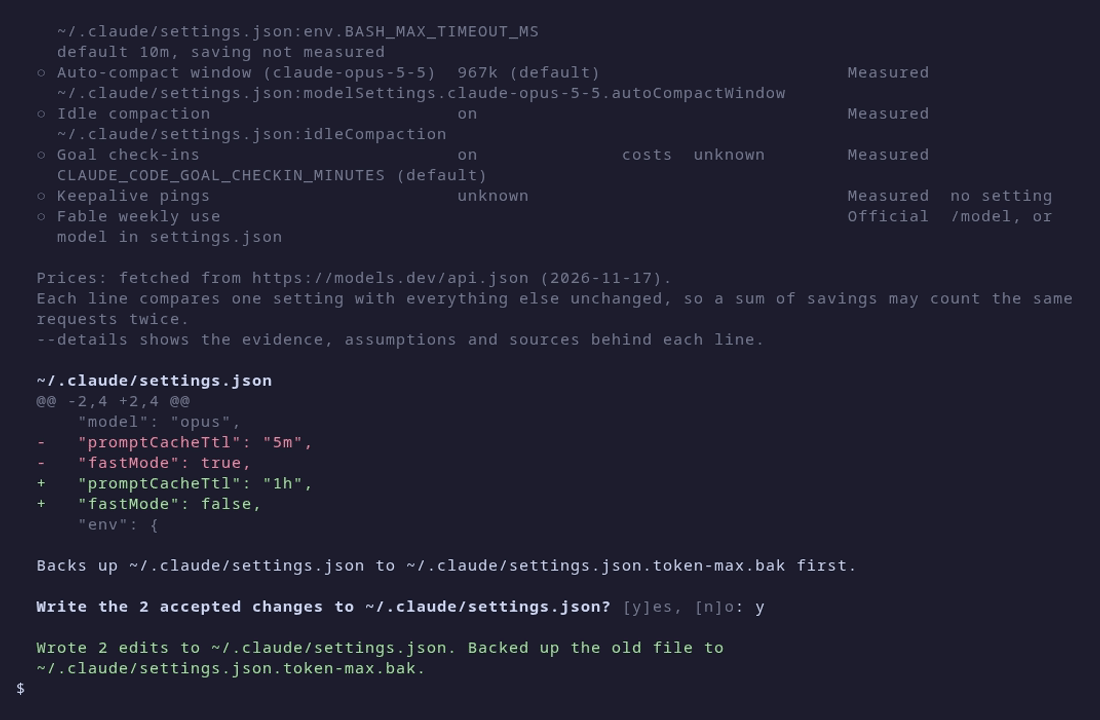
The recording runs on synthetic transcripts, not a real host.
- Reads every transcript. Claude Code, Codex and T3 Code record each request's token counts. token-max streams them a line at a time and keeps the counts, times and IDs, never a prompt or a reply.
- Replays the cache. For every request it rebuilds what was cached, when it was written and whether it had expired by the next one, then plays the same sessions again under the other setting.
- Prices both. At public API prices from
https://models.dev/api.json, its only network request unless you name other machines with--ssh. What it can't price stays unknown, never zero. Each line says whether it is Measured, Official guidance or the maintainer's Opinion.
Then token-max doctor offers each change, shows the edit, and writes it only
after a yes, first copying the file to a
.token-max.bak backup
unless git already keeps it. Replay semantics
has the accounting.
curl -LsSf https://max.kixel.ai/install.sh | shOn Windows, in PowerShell:
irm https://max.kixel.ai/install.ps1 | iexEach GitHub release has prebuilt binaries for
Linux (x86_64 and arm64, statically linked), macOS (Apple silicon and Intel)
and Windows (x86_64). install.sh and install.ps1 are the release's
installers, which put token-max in ~/.local/bin by default. run.sh and
run.ps1 download the binary to a cache instead, check it against the
release's checksum, and run token-max doctor; the
reference
says how to pass it options.
cargo binstall token-max downloads the same binary, and
cargo install --locked token-max builds it. On Linux and Apple silicon,
Nix builds it from source:
nix run github:kixel-ai/token-max -- doctortoken-max doctor # every Claude Code and Codex profile on this host
token-max doctor --since 2026-11-01 # only sessions from that date on
token-max doctor --details # the evidence behind every line
token-max doctor --ssh devbox --include-local # this host and devbox, each change made on its own host
token-max doctor --help| Setting or feature | What the report says |
|---|---|
| Prompt cache TTL (5m or 1h) | Which lifetime would have cost less on your sessions |
| Auto-compact window | Whether a different window would have cost less, summaries included |
| Idle compaction | Whether compacting sessions you walked away from paid for itself |
| Tools, skills and MCP servers | What each cost to send with every request, and how often it was used |
| Instruction files | What each CLAUDE.md or AGENTS.md cost, beside the provider's size guidance |
| Fast mode | What the premium cost; recommended off |
| Main-session effort | What each model and effort cost, beside the provider's guidance; max recommended down to xhigh, low worth considering raising |
| Auto memory | What loading, reading and writing it cost, and how often it was used; worth considering off |
| Prompt suggestions, recaps, check-ins | What each background feature cost, where it can be estimated |
| Bash timeout cap | Whether long foreground waits let the cache expire |
| Keepalive pings | Whether pinging idle sessions would beat the cache misses |
| Subagent types | What each cost, which model and effort it ran on, and the same tokens on the cheapest current model, beside Anthropic's model guide |
| Fable weekly use | Each week's Fable spend beside Anthropic's rule that, on Max and Ultra plans, Fable can use up to half the weekly limit |
See the reference for how to read each line, and its sections for each check.
- Reference:
every flag, report section and check, including
--ssh, T3 Code and thetoken-max sessionsexport of each session's cost, branches and repositories, from this host or over SSH. - Replay semantics: the accounting, assumptions, sources and limits.
- Plans: the work still to come.
- To work on it, run
nix develop, thenjust check. See CONTRIBUTING.md.